Publications
2026
- ACL
 Is Chain-of-Thought Reasoning of LLMs a Mirage? A Data Distribution LensChengshuai Zhao, Zhen Tan, Pingchuan Ma, and 5 more authorsIn Findings of the Association for Computational Linguistics: ACL 2026, 2026
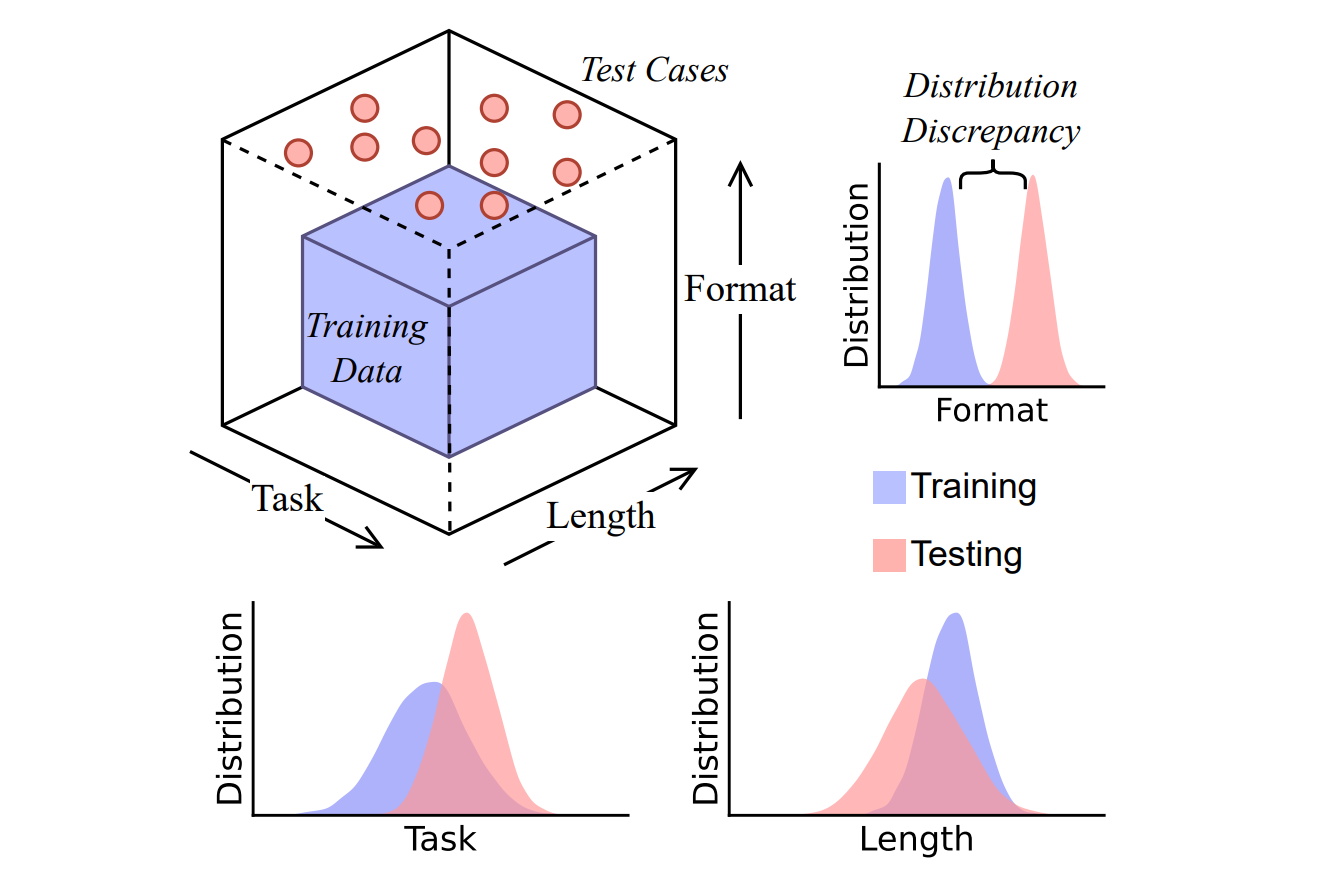
Chain-of-Thought (CoT) prompting has been shown to improve Large Language Model (LLM) performance on various tasks. With this approach, LLMs appear to produce human-like reasoning steps before providing answers (a.k.a., CoT reasoning), which often leads to the perception that they engage in deliberate inferential processes. However, some initial findings suggest that CoT reasoning may be more superficial than it appears, motivating us to explore further. In this paper, we study CoT reasoning via a data distribution lens and investigate if CoT reasoning reflects a structured inductive bias learned from in-distribution data, allowing the model to conditionally generate reasoning paths that approximate those seen during training. Thus, its effectiveness is fundamentally bounded by the degree of distribution discrepancy between the training data and the test queries. With this lens, we dissect CoT reasoning via three dimensions: task, length, and format. To investigate each dimension, we design DataAlchemy, an isolated and controlled environment to train LLMs from scratch and systematically probe them under various distribution conditions. Our results reveal that CoT reasoning is a brittle mirage that vanishes when it is pushed beyond training distributions. This work offers a deeper understanding of why and when CoT reasoning fails, emphasizing the ongoing challenge of achieving genuine and generalizable reasoning.
@inproceedings{zhao2025chain, title = {Is Chain-of-Thought Reasoning of LLMs a Mirage? A Data Distribution Lens}, author = {Zhao, Chengshuai and Tan, Zhen and Ma, Pingchuan and Li, Dawei and Jiang, Bohan and Wang, Yancheng and Yang, Yingzhen and Liu, Huan}, booktitle = {Findings of the Association for Computational Linguistics: ACL 2026}, year = {2026}, huggingface = {https://huggingface.co/papers/2508.01191}, } - WWW
 Causality Guided Representation Learning for Cross-Style Hate Speech DetectionChengshuai Zhao, Shu Wan, Paras Sheth, and 3 more authorsIn Proceedings of the ACM Web Conference 2026, 2026
This paper was accepted by WWW 2026 as an oral presentation, and by the UCRL Workshop at ICLR 2026
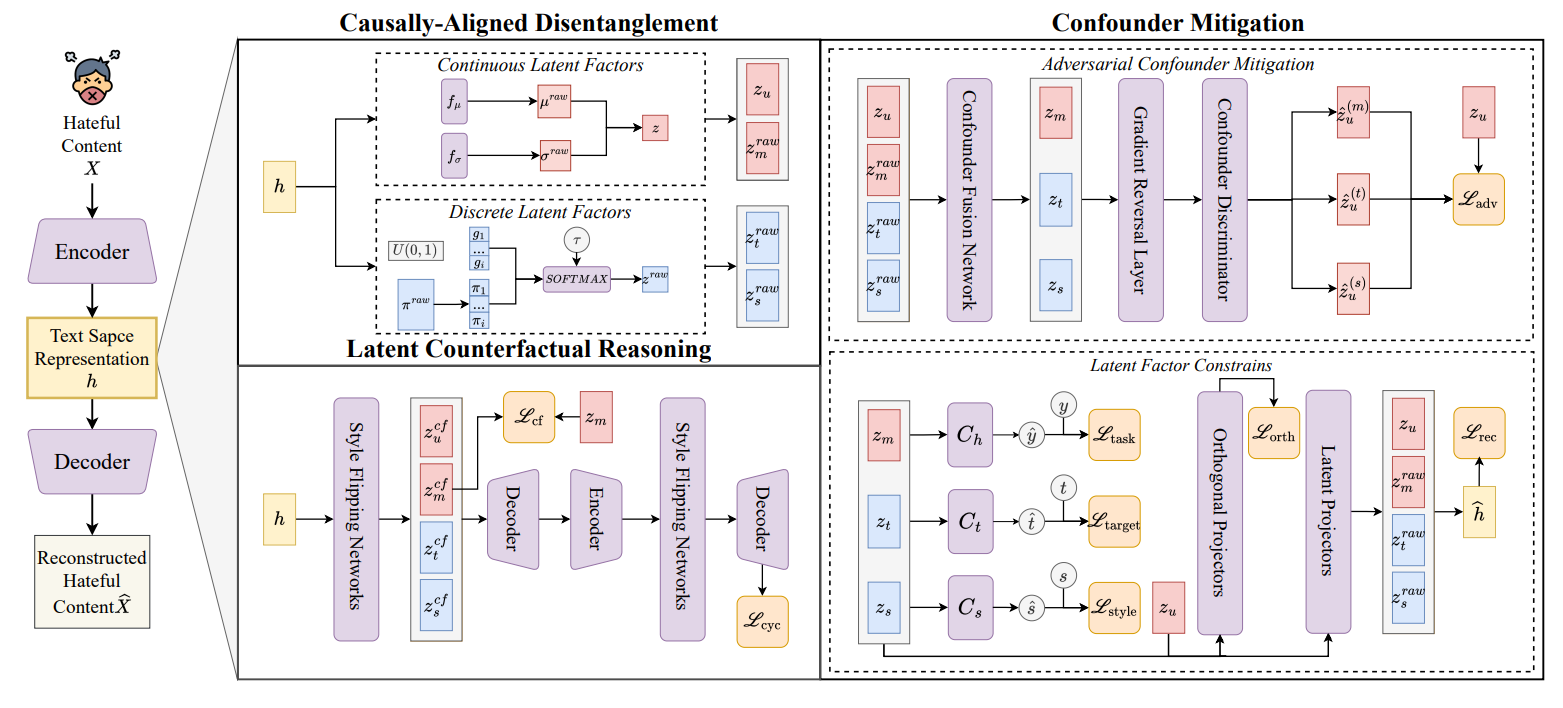
The proliferation of online hate speech poses a significant threat to the harmony of the web. While explicit hate is easily recognized through overt slurs, implicit hate speech is often conveyed through sarcasm, irony, stereotypes, or coded language – making it harder to detect. Existing hate speech detection models, which predominantly rely on surface-level linguistic cues, fail to generalize effectively across diverse stylistic variations. Moreover, hate speech spread on different platforms often targets distinct groups and adopts unique styles, potentially inducing spurious correlations between them and labels, further challenging current detection approaches. Motivated by these observations, we hypothesize that the generation of hate speech can be modeled as a causal graph involving key factors: contextual environment, creator motivation, target, and style. Guided by this graph, we propose CADET, a causal representation learning framework that disentangles hate speech into interpretable latent factors and then controls confounders, thereby isolating genuine hate intent from superficial linguistic cues. Furthermore, CADET allows counterfactual reasoning by intervening on style within the latent space, naturally guiding the model to robustly identify hate speech in varying forms. CADET demonstrates superior performance in comprehensive experiments, highlighting the potential of causal priors in advancing generalizable hate speech detection.
@inproceedings{zhao2026causality, title = {Causality Guided Representation Learning for Cross-Style Hate Speech Detection}, author = {Zhao, Chengshuai and Wan, Shu and Sheth, Paras and Patwa, Karan and Candan, K. Selçuk and Liu, Huan}, booktitle = {Proceedings of the ACM Web Conference 2026}, publisher = {ACM}, year = {2026}, } - PAKDD
 CAMO: Causality-Guided Adversarial Multimodal Domain Generalization for Crisis ClassificationPingchuan Ma, Chengshuai Zhao, Bohan Jiang, and 5 more authorsIn Advances in Knowledge Discovery and Data Mining: 30th Pacific-Asia Conference, PAKDD 2026, 2026
This paper was accepted by PAKDD 2026 as an oral presentation
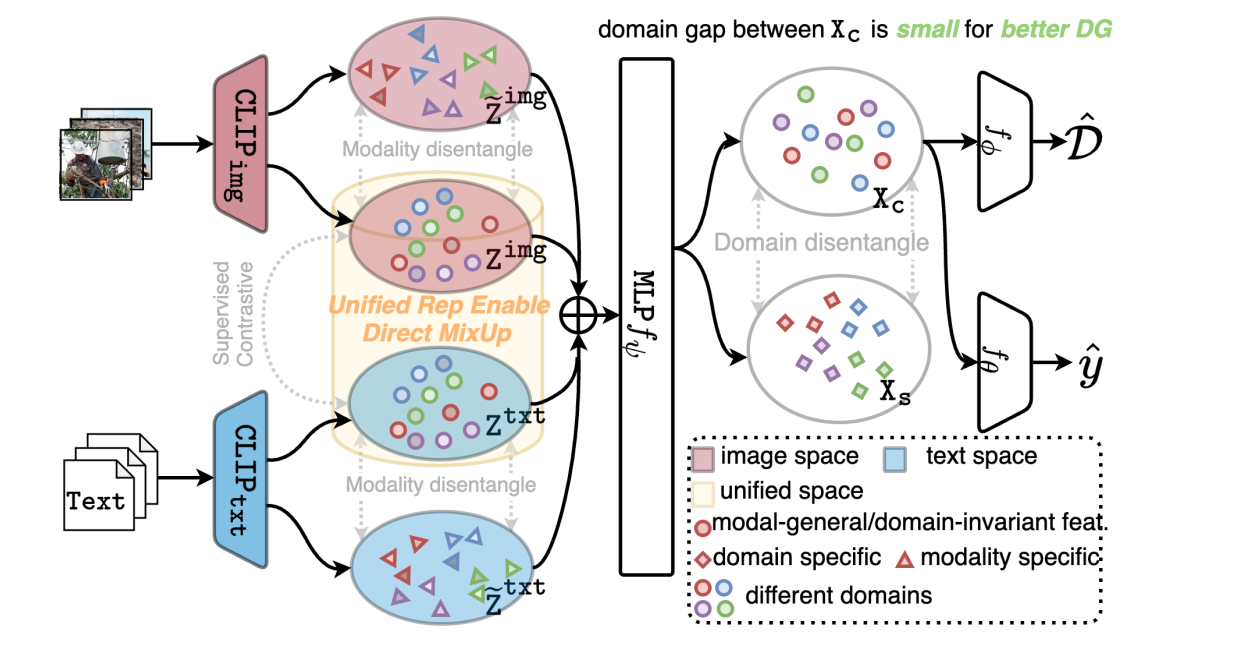
Crisis classification in social media aims to extract actionable disaster-related information from multimodal posts, which is a crucial task for enhancing situational awareness and facilitating timely emergency responses. However, the wide variation in crisis types makes achieving generalizable performance across unseen disasters a persistent challenge. Existing approaches primarily leverage deep learning to fuse textual and visual cues for crisis classification, achieving numerically plausible results under in-domain settings. However, they exhibit poor generalization across unseen crisis types because they 1. do not disentangle spurious and causal features, resulting in performance degradation under domain shift, and 2. fail to align heterogeneous modality representations within a shared space, which hinders the direct adaptation of established single-modality domain generalization (DG) techniques to the multimodal setting. To address these issues, we introduce a causality-guided multimodal domain generalization (MMDG) framework that combines adversarial disentanglement with unified representation learning for crisis classification. The adversarial objective encourages the model to disentangle and focus on domain-invariant causal features, leading to more generalizable classifications grounded in stable causal mechanisms. The unified representation aligns features from different modalities within a shared latent space, enabling single-modality DG strategies to be seamlessly extended to multimodal learning. Experiments on the different datasets demonstrate that our approach achieves the best performance in unseen disaster scenarios.
@inproceedings{ma2026camo, title = {CAMO: Causality-Guided Adversarial Multimodal Domain Generalization for Crisis Classification}, author = {Ma, Pingchuan and Zhao, Chengshuai and Jiang, Bohan and Vishnubhatla, Saketh and Jeong, Ujun and Beigi, Alimohammad and Raglin, Adrienne and Liu, Huan}, booktitle = {Advances in Knowledge Discovery and Data Mining: 30th Pacific-Asia Conference, PAKDD 2026}, publisher = {Springer}, year = {2026}, } - ECML-PKDD
 EssayCBM: Rubric-Aligned Concept Bottleneck Models for Transparent Essay GradingKumar Satvik Chaudhary, Chengshuai Zhao, Fan Zhang, and 3 more authorsIn Machine Learning and Knowledge Discovery in Databases: European Conference, ECML PKDD 2026, 2026
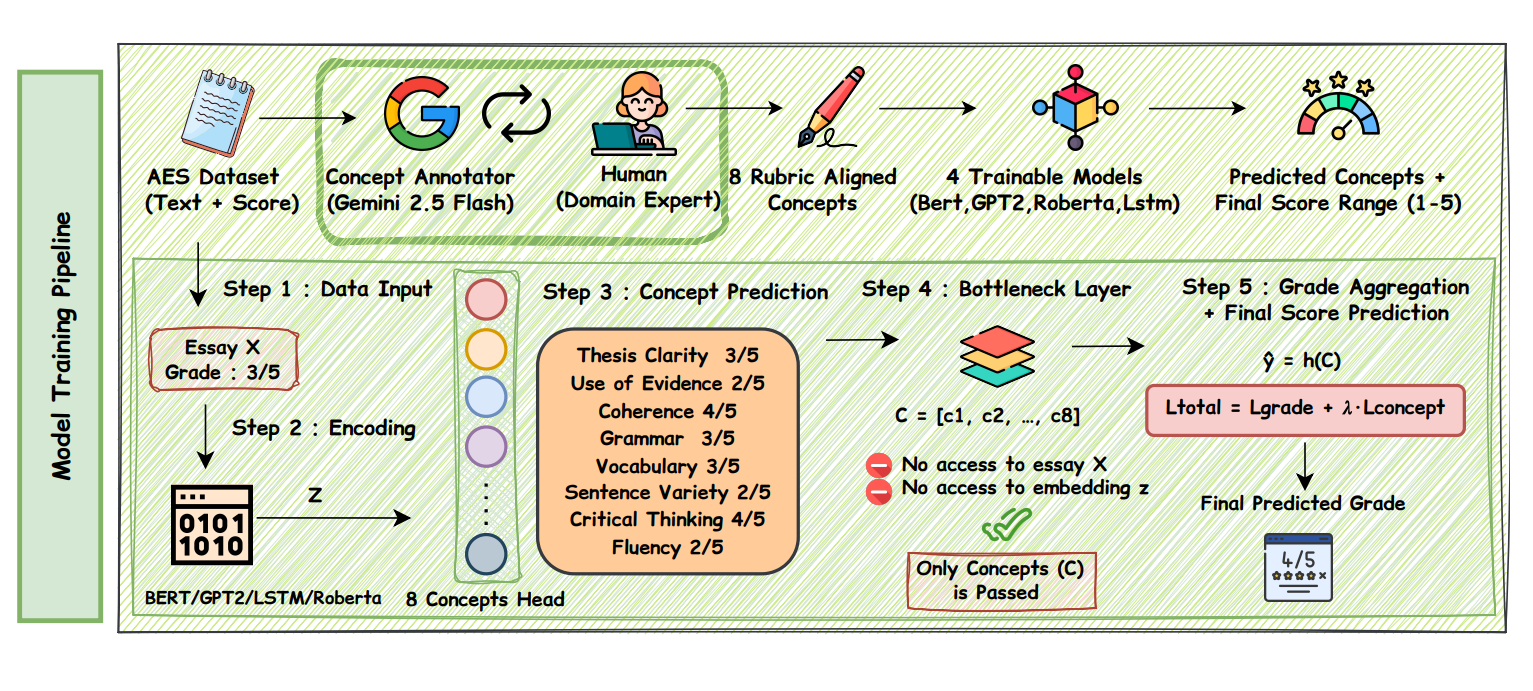
Automated essay scoring (AES) has advanced significantly with neural language models, yet most systems remain opaque, offering little visibility into how grades are produced. In educational settings, instructors must be able to understand, trust, and occasionally override the automated grading decisions. We introduce EssayCBM, a rubric-aligned concept bottleneck framework that decomposes essay evaluation into eight interpretable writing concepts before computing the final score. Unlike direct LLM-based grading approaches, EssayCBM learns an explicit and auditable mapping from writing concepts to grades, allowing instructors to inspect and adjust rubric-level predictions during grading. EssayCBM matches neural AES baselines while making grading decisions transparent and directly editable at the rubric level. We further present an interactive system that demonstrates this capability by allowing instructors to inspect and modify concept predictions in real time.
@inproceedings{chaudhary2026essaycbm, title = {EssayCBM: Rubric-Aligned Concept Bottleneck Models for Transparent Essay Grading}, author = {Chaudhary, Kumar Satvik and Zhao, Chengshuai and Zhang, Fan and Agrawal, Garima and Deng, Yuli and Liu, Huan}, booktitle = {Machine Learning and Knowledge Discovery in Databases: European Conference, ECML PKDD 2026}, publisher = {Springer}, year = {2026}, } - ICLR
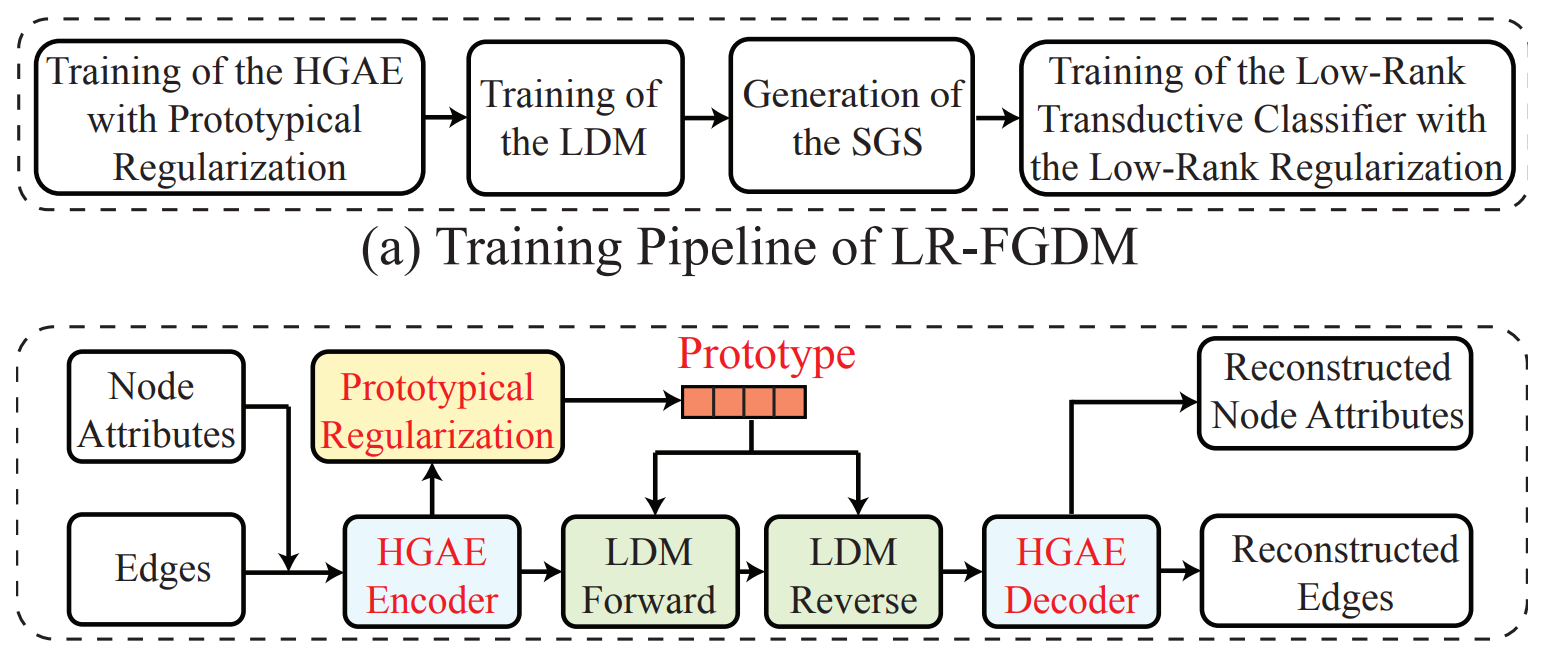 Low-Rank Few-Shot Node Classification by Node-Level Graph DiffusionYancheng Wang, Chengshuai Zhao, Dongfang Sun, and 2 more authorsIn The Fourteenth International Conference on Learning Representations, 2026
In this paper, we propose a novel node-level graph diffusion method with low-rank feature learning for few-shot node classification (FSNC), termed Low-Rank Few-Shot Graph Diffusion Model or LR-FGDM. LR-FGDM first employs a novel Few-Shot Graph Diffusion Model (FGDM) as a node-level graph generative method to generate an augmented graph with an enlarged support set, then performs low-rank transductive classification to obtain the few-shot node classification results. Our graph diffusion model, FGDM, comprises two components, the Hierarchical Graph Autoencoder (HGAE) with an efficient hierarchical edge reconstruction method and a new prototypical regularization, and the Latent Diffusion Model (LDM). The low-rank regularization is robust to the noise inherently introduced by the diffusion model and empirically inspired by the Low Frequency Property. We also provide a strong theoretical guarantee justifying the low-rank regularization for the transductive classification in few-shot learning. To further enhance the performance of LR-FGDM, we introduce LRA-LR-FGDM with a novel efficient LR-Attention layer, or the LRA layer, which applies self-attention to the output of the LR-FGDM encoder. The LRA layer further reduces the kernel complexity of LR-FGDM and contributes to a tighter generalization bound, leading to improved performance. Extensive experimental results evidence the effectiveness of LR-FGDM for few-shot node classification, which outperforms the current state-of-the-art. The code of the LR-FGDM is available at https://github.com/Statistical-Deep-Learning/LR-FGDM.
@inproceedings{wang2026lowrank, title = {Low-Rank Few-Shot Node Classification by Node-Level Graph Diffusion}, author = {Wang, Yancheng and Zhao, Chengshuai and Sun, Dongfang and Liu, Huan and Yang, Yingzhen}, booktitle = {The Fourteenth International Conference on Learning Representations}, year = {2026}, } - ICLR
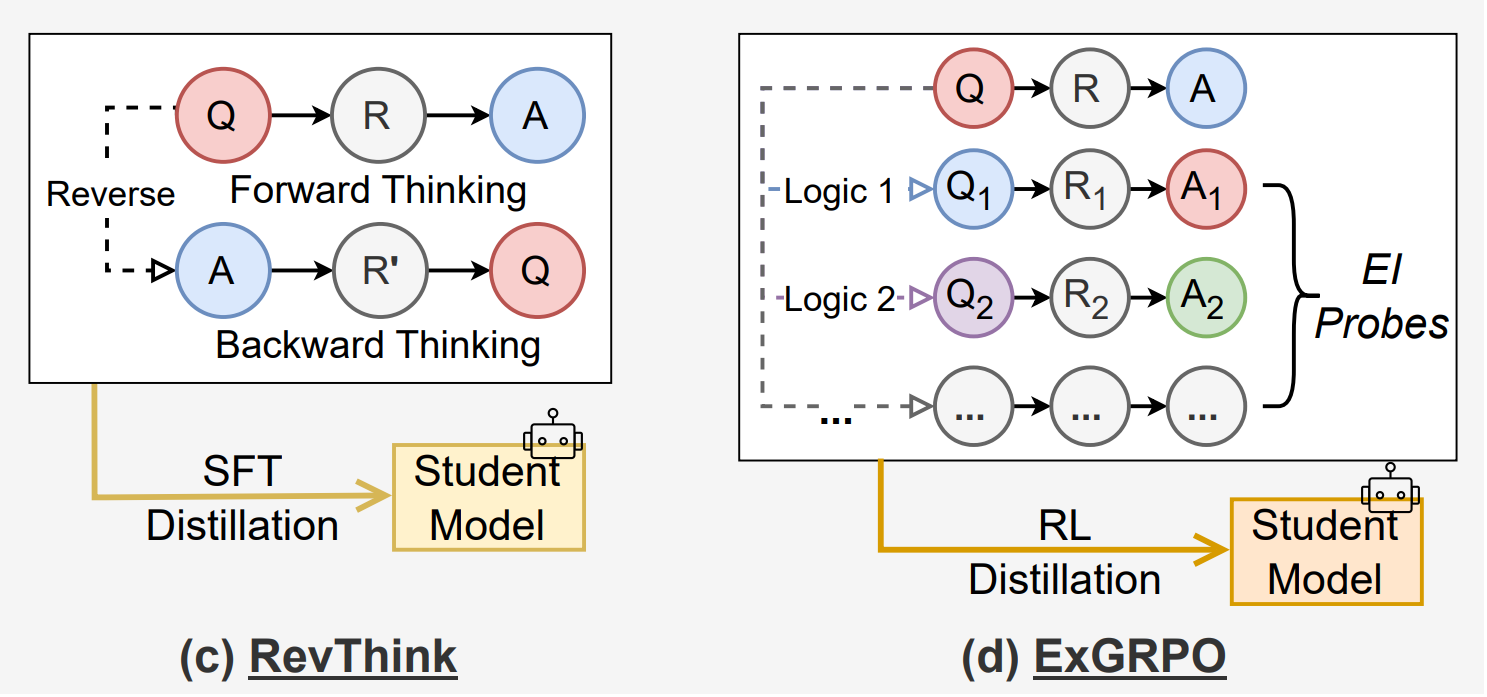 Probing to Refine: Reinforcement Distillation of LLM Reasoners via Explanatory InversionZhen Tan, Chengshuai Zhao, Song Wang, and 3 more authorsIn The Fourteenth International Conference on Learning Representations, 2026
Distilling robust reasoning capabilities from large language models (LLMs) into smaller, computationally efficient student models remains an unresolved challenge. Despite recent advances, distilled models frequently suffer from superficial pattern memorization and subpar generalization. To overcome these limitations, we introduce a novel distillation framework that moves beyond simple mimicry to instill a deeper conceptual understanding. Our framework features two key innovations. \underline(\textit(First)), to address pattern memorization, Explanatory Inversion (EI) generates targeted “explanatory probes” that compel the student to articulate the underlying logic behind an answer, rather than just memorizing it. \underline(\textit(Second)), to improve generalization, Explanatory GRPO (\texttt(EXGRPO)) uses a reinforcement learning algorithm with a novel Dialogue Structure Utility Bonus, which explicitly rewards the student for maintaining a coherent reasoning process across these probes. Extensive evaluations on 12 datasets demonstrate significant improvements. Using Gemma-7b as the student model, our method yields an average \textbf(20.39%) increase over zero-shot performance and a \textbf(6.02%) improvement over the state-of-the-art distillation baselines. Moreover, models distilled with our method show remarkable training efficiency (e.g., surpassing vanilla fine-tuning with \textbf(10-25%) training data) and strong generalization to out-of-distribution tasks. Implementation is released at https://github.com/Zhen-Tan-dmml/ExGRPO.git.
@inproceedings{tan2026probing, title = {Probing to Refine: Reinforcement Distillation of LLM Reasoners via Explanatory Inversion}, author = {Tan, Zhen and Zhao, Chengshuai and Wang, Song and Li, Jundong and Chen, Tianlong and Liu, Huan}, booktitle = {The Fourteenth International Conference on Learning Representations}, year = {2026}, } - Journal
 Automating Content Analysis With Multiple LLM Agents: Impacts of Agent Attributes and Human–AI CollaborationXinyan Zhao, Chengshuai Zhao, Mordecai Mengesteab, and 4 more authorsSocial Science Computer Review, 2026
Emerging research in computational social science has applied LLMs to automate content analysis, often by prompting a single model to act as a human coder. While a single LLM may suffice for a few manifest variables, it still falls short on diverse latent constructs. And the impact of LLM agent attributes on measurement outcomes remains unclear, limiting their validity for communication research. Drawing upon the literature on interacting agents and communication, this study examines the impact of agent diversity, agent open-mindedness, and human–AI collaboration (HAIC) in a multi-LLM-agent system for automated content analysis. The results demonstrate reliable and accurate measurement of four communication variables across three datasets, with improved performance following agent discussion. Additionally, agent open-mindedness, but not agent diversity, significantly affects measurement outcomes. These results highlight the potential of multi-LLM-agent systems for automated content analysis and suggest the importance of considering agent attributes and values in system design.
@article{zhao2026automating, title = {Automating Content Analysis With Multiple LLM Agents: Impacts of Agent Attributes and Human–AI Collaboration}, author = {Zhao, Xinyan and Zhao, Chengshuai and Mengesteab, Mordecai and Wong, Chau-Wai and Zhan, Mengqi and Tan, Zhen and Chen, Tianlong}, journal = {Social Science Computer Review}, year = {2026}, publisher = {SAGE Publications}, } - Journal
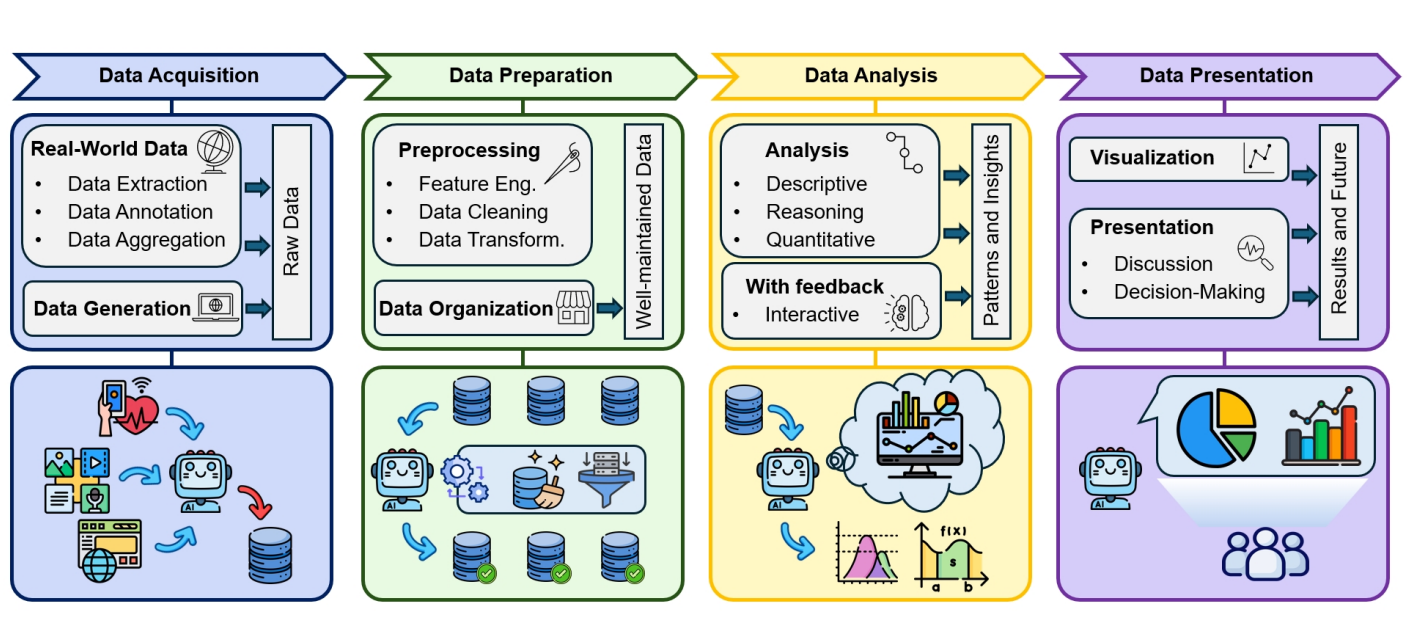 Large Language Models for Data Science: A SurveySong Wang, Zhen Tan, Zihan Chen, and 11 more authorsACM SIGKDD Explorations Newsletter, 2026
Data science is an interdisciplinary field that focuses on extracting knowledge from raw data using statistical analysis and machine learning techniques. However, as data continues to grow in scale and complexity, data scientists face increasing challenges in handling unstructured data, automating workflows, and scaling analytical processes. The advancements of large language models (LLMs) present an unprecedented opportunity to enhance and streamline data science tasks by enabling automation and augmentation of key processes in the data science pipeline. This survey contributes to four core aspects: the role of LLMs in the data science cycle, specialized domain applications, challenges and limitations, and social impact and future directions. Furthermore, we introduce a structured framework defining how LLMs contribute to each stage of data science, provide an in-depth discussion on their applications in key domains such as healthcare and finance, analyze key obstacles such as data quality and model interpretability, and explore ethical concerns and future research opportunities. Serving as a comprehensive resource, this survey aims to assist researchers and practitioners in understanding and utilizing LLMs to advance modern data science methodologies. We provide the paper list of LLMs for data science at https://github.com/SongW-SW/awesome-LLM-DS.
@article{wang2026survey, title = {Large Language Models for Data Science: A Survey}, author = {Wang, Song and Tan, Zhen and Chen, Zihan and Li, Dawei and Zhu, Yaochen and Jiang, Bohan and He, Yinhan and Zhao, Chengshuai and Lei, Zhenyu and Sheth, Paras and Li, Lichi and Ting, Lo Pang-Yun and Li, Jundong and Liu, Huan}, journal = {ACM SIGKDD Explorations Newsletter}, year = {2026}, publisher = {ACM}, } - LERN
 Epistemic Cognition and Uncertainty Navigation with a Domain-Specific AI Chatbot in STEM EducationYiwen Li, Chengshuai Zhao, Garima Agrawal, and 4 more authorsIn Proceedings of the Learning Engineering Research Network Convening (LERN 2026), 2026
Domain-specific AI chatbots are increasingly embedded in STEM courses, yet little is known about how students judge, interpret, and act on AI-generated feedback during learning. This study examines students’ epistemic cognition when interacting with Cyberbot, a domain-specific AI-powered chatbot integrated into a cloud computing course. Drawing on post-course semi-structured interviews with twelve students, we analyze how learners articulate epistemic aims, evaluate the correctness and reliability of AI feedback, and navigate uncertainty when deciding whether to revise or persist in their problem-solving approaches. Findings indicate that Cyberbot does not eliminate uncertainty for learners; instead, it reorganizes epistemic work by shifting responsibility toward verification, judgment, and decision-making. Students demonstrated calibrated trust, actively cross-checking AI responses with other sources and using the chatbot primarily for epistemic verification rather than open-ended exploration. These results highlight the importance of examining epistemic processes when evaluating AI-supported learning.
@inproceedings{li2026epistemic, title = {Epistemic Cognition and Uncertainty Navigation with a Domain-Specific AI Chatbot in STEM Education}, author = {Li, Yiwen and Zhao, Chengshuai and Agrawal, Garima and Deng, Yuli and Park, Jongchan and Chen, Ying-Chih and Liu, Huan}, booktitle = {Proceedings of the Learning Engineering Research Network Convening (LERN 2026)}, year = {2026}, } - SDM
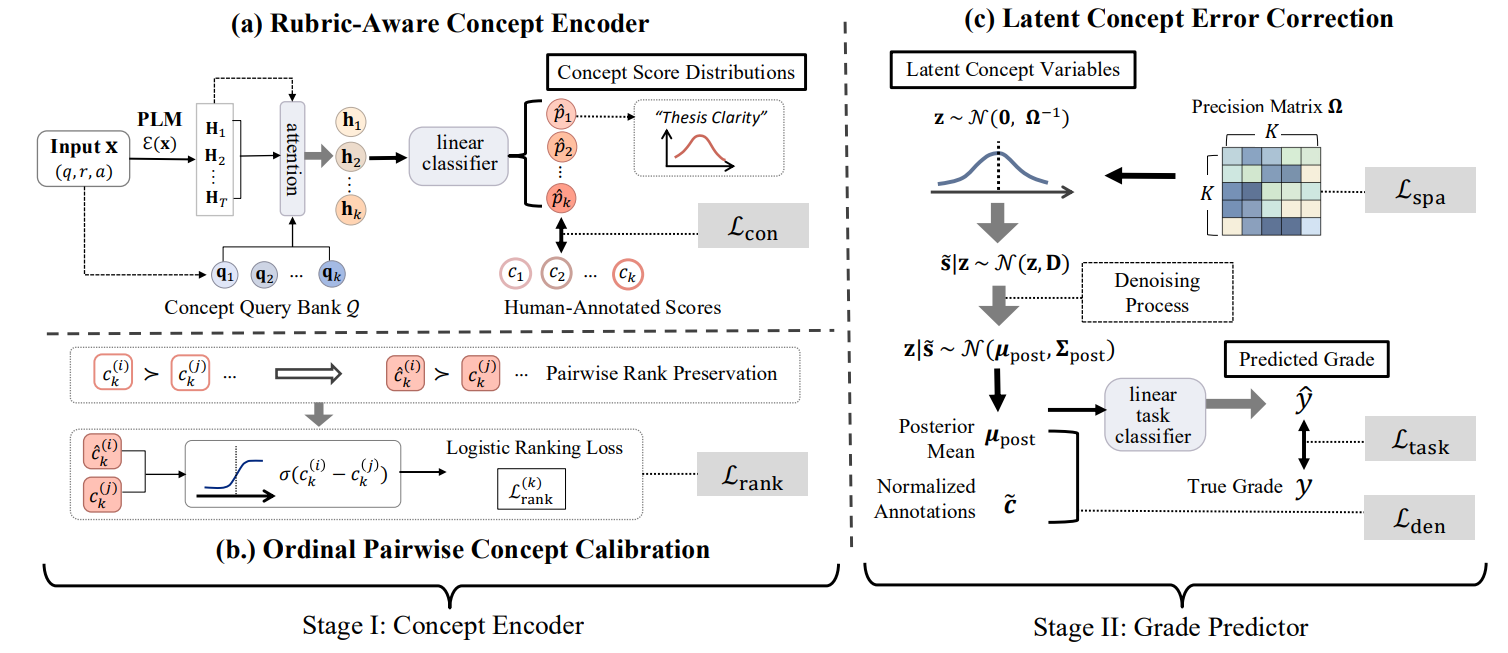 REC-CBM: Rubric-Aware Error-Correction Concept Bottleneck Models for Trustworthy Open-Ended GradingChengshuai Zhao, Fan Zhang, Kumar Satvik Chaudhary, and 4 more authorsIn Proceedings of the 2026 SIAM International Conference on Data Mining (SDM), 2026
Open-ended grading is central to equitable and personalized education, yet manual grading remains time-consuming and costly, underscoring the need for automated grading systems. Although recent neural and large language model (LLM) based systems have demonstrated superior performance, they are typically black-box models whose scoring processes and rationales are difficult for educators to verify and trust. Concept bottleneck models (CBMs) have emerged as a promising approach by routing predictions through human-interpretable concepts, providing a mechanistic guarantee of transparency. However, standard CBMs are not tailored to open-ended grading: they do not explicitly model fine-grained rubric dimensions, inadequately capture the ordinal semantics of scoring scales, and neglect inherent reliability issues in human concept annotations. To address these limitations, we propose REC-CBM, a rubric-aware error-correction concept bottleneck model for trustworthy open-ended grading. REC-CBM introduces a rubric-aware concept encoder that learns concept-specific representations over responses and an ordinal pairwise calibration objective that preserves ranking structure among rubric dimensions. It further incorporates a latent concept error-correction module that denoises concept predictions before final grade prediction while preserving interpretability. Comprehensive experiments on publicly available datasets show that REC-CBM consistently improves grading performance and produces more faithful concept-level reasoning than both state-of-the-art baselines. Further analyses validate the contribution of each component and demonstrate the applicability in realistic educational settings. Overall, this work provides a practical, interpretable grading solution that enables educators to inspect, intervene in, and trust automated decisions, advancing more transparent and trustworthy education.
@inproceedings{zhao2026reccbm, title = {REC-CBM: Rubric-Aware Error-Correction Concept Bottleneck Models for Trustworthy Open-Ended Grading}, author = {Zhao, Chengshuai and Zhang, Fan and Chaudhary, Kumar Satvik and Li, Yiwen and Ting, Lo Pang-Yun and Chen, Ying-Chih and Liu, Huan}, booktitle = {Proceedings of the 2026 SIAM International Conference on Data Mining (SDM)}, publisher = {SIAM}, year = {2026}, } - arXiv
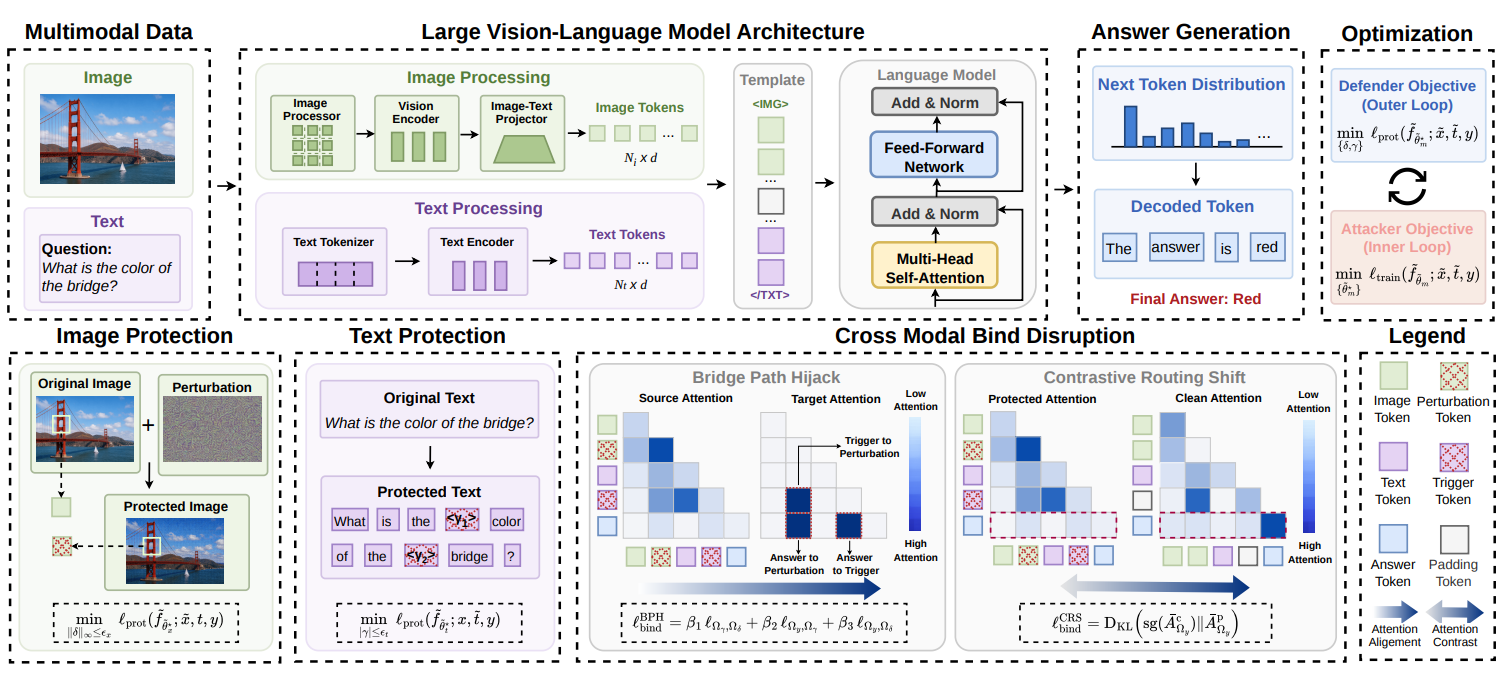 To See is Not to Learn: Protecting Multimodal Data from Unauthorized Fine-Tuning of Large Vision-Language ModelChengshuai Zhao, Zhen Tan, Dawei Li, and 2 more authorsarXiv preprint arXiv:2605.14291, 2026
The rapid advancement of Large Vision-Language Models (LVLMs) is increasingly accompanied by unauthorized scraping and training on multimodal web data, posing severe copyright and privacy risks to data owners. Existing countermeasures, such as machine unlearning and watermarks, are inherent post-hoc approaches that act only after intellectual property infringement has already occurred. In this work, we propose MMGuard to empower data owners to proactively protect their multimodal data against unauthorized LVLM fine-tuning. MMGuard generates unlearnable examples by injecting human-imperceptible perturbations that actively exploit the learning dynamics of LVLMs. By minimizing the training loss, the perturbation creates an optimization shortcut, causing the model to overfit to the noise and thereby degrading downstream performance when the perturbation is absent during inference. To further strengthen this defense, MMGuard introduces a cross-modal binding disruption, strategically shifting LVLM attention to enforce a spurious correlation between the noise and the training target with theoretical guarantees. Enhanced by an ensemble learning strategy for cross-model transferability, MMGuard is evaluated against nine open-source LVLMs across six datasets. Our comprehensive results demonstrate effective, stealthy, and robust protection under white-box, gray-box, and black-box threat models, establishing a mechanistic advantage in proactively defending against aggressive fine-tuning exploitation.
@article{zhao2026see, title = {To See is Not to Learn: Protecting Multimodal Data from Unauthorized Fine-Tuning of Large Vision-Language Model}, author = {Zhao, Chengshuai and Tan, Zhen and Li, Dawei and Yu, Zhiyuan and Liu, Huan}, journal = {arXiv preprint arXiv:2605.14291}, year = {2026}, } - arXiv
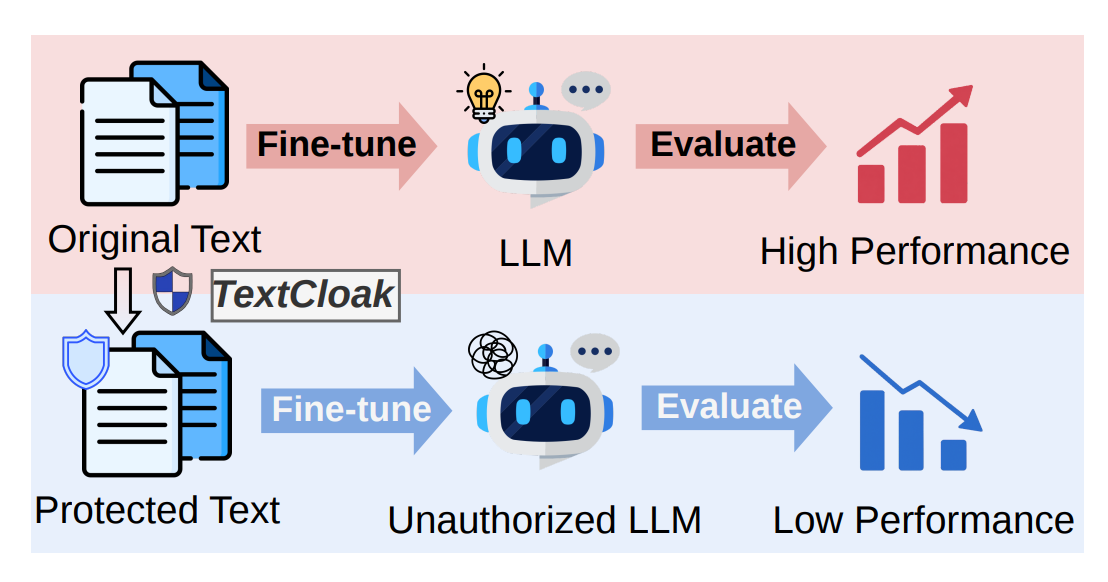 TextCloak: Safeguarding Data from Unauthorized LLM Fine-Tuning via RL-Driven Unlearnable ExamplesChengshuai Zhao, Pingchuan Ma, Dawei Li, and 4 more authorsarXiv preprint arXiv:2607.28862, 2026
The rapid development of Large Language Models (LLMs) has led to significant advances across a wide range of language tasks, while simultaneously raising growing concerns about unauthorized data exploitation and privacy leakage. Unlearnable examples (UEs) offer a promising defense by introducing carefully designed perturbations into data such that models trained on them exhibit degraded utility. However, existing methods for text protection are primarily designed for classification tasks (e.g., sentiment analysis) in discriminative language models and often rely on injecting class-specific linguistic cues, which limits their effectiveness in the open-ended generation settings of LLMs. In this work, we propose TextCloak, an RL-driven framework for protecting textual data against unauthorized LLM exploitation. TextCloak employs a generative policy that transforms batches of clean text into unlearnable examples while preserving semantic fidelity and linguistic naturalness. To optimize the policy, we introduce GRPO-UE, which rewards generated unlearnable text based on the downstream degradation they induce in fine-tuned surrogate LLMs and updates the generator parameters via group-relative policy optimization. This bi-level optimization enables the generator to discover generalizable protective patterns beyond class-specific cues. Comprehensive experiments on six publicly available datasets and nine state-of-the-art LLMs demonstrate that TextCloak consistently impairs unauthorized fine-tuning while maintaining text utility for legitimate use. Further analyses establish its transferability and robustness across model architectures, training configurations, and adaptive attacks, highlighting its broad applicability as a practical defense against unauthorized LLM exploitation.
@article{zhao2026textcloak, title = {TextCloak: Safeguarding Data from Unauthorized LLM Fine-Tuning via RL-Driven Unlearnable Examples}, author = {Zhao, Chengshuai and Ma, Pingchuan and Li, Dawei and Jiang, Bohan and Yu, Zhiyuan and Tan, Zhen and Liu, Huan}, journal = {arXiv preprint arXiv:2607.28862}, year = {2026}, } - arXiv
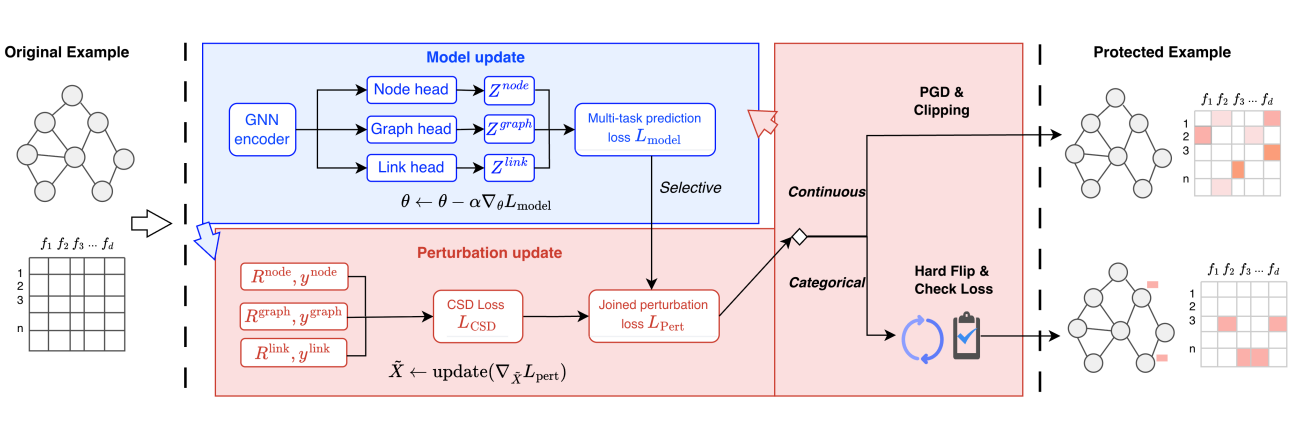 MUGEN: Generating Unlearnable Graph Examples for Multiple Learning TasksZiyan Liu, Chengshuai Zhao, and Huan LiuarXiv preprint arXiv:2609.00696, 2026
Graph data across diverse domains can expose valuable relational information to unauthorized representation learning, creating a pressing need for protection against such misuse. Unlearnable examples offer a data-level defense by perturbing a training release so that models trained on it fail to generalize to clean data. Existing methods generate unlearnable graph examples for only a specified downstream task. Consequently, a release protected against one task may remain learnable for other plausible uses, including node classification, graph classification, and link prediction, which the data owner cannot anticipate. We introduce MUGEN, to our knowledge the first framework for generating unlearnable graph examples that jointly protect all enabled tasks. From one clean dataset, MUGEN produces a single feature-perturbed release that protects every enabled task through a shared GNN encoder and task-specific heads. We devise a Task-Aligned Separability Objective (TASO), which leverages task prediction and classwise separability to strengthen unlearnability and its transfer across GNN backbones and enabled tasks. We further introduce Type-Adaptive Perturbation (TAP), which tailors perturbation optimization to node-attribute type, with direct search over feasible hard flips that accept only loss-improving updates for discrete node attributes and customized gradient-based updates for continuous node features, thereby enabling strong unlearnability across both settings. Experiments across five benchmarks, four backends and three learning paradigms demonstrate that MUGEN generates transferable unlearnable graph examples across GNN backbones and all three tasks, and remains effective under adversarial training and data augmentation.
@article{liu2026mugen,
  title = {MUGEN: Generating Unlearnable Graph Examples for Multiple Learning Tasks},
  author = {Liu, Ziyan and Zhao, Chengshuai and Liu, Huan},
  journal = {arXiv preprint arXiv:2609.00696},
  year = {2026},
}
2025
- EMNLP
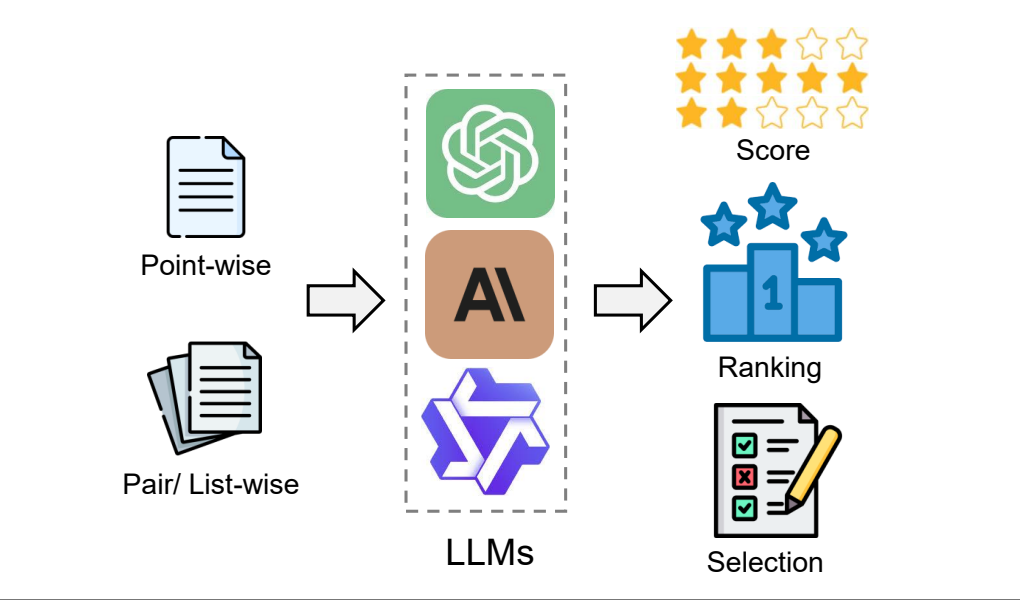 From generation to judgment: Opportunities and challenges of llm-as-a-judgeDawei Li, Bohan Jiang, Liangjie Huang, and 8 more authorsIn Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, 2025
This paper was accepted as an EMNLP 2025 main conference paper (Oral)
Assessment and evaluation have long been critical challenges in artificial intelligence (AI) and natural language processing (NLP). However, traditional methods, whether matching-based or embedding-based, often fall short of judging subtle attributes and delivering satisfactory results. Recent advancements in Large Language Models (LLMs) inspire the "LLM-as-a-judge" paradigm, where LLMs are leveraged to perform scoring, ranking, or selection across various tasks and applications. This paper provides a comprehensive survey of LLM-based judgment and assessment, offering an in-depth overview to advance this emerging field. We begin by giving detailed definitions from both input and output perspectives. Then we introduce a comprehensive taxonomy to explore LLM-as-a-judge from three dimensions: what to judge, how to judge and where to judge. Finally, we compile benchmarks for evaluating LLM-as-a-judge and highlight key challenges and promising directions, aiming to provide valuable insights and inspire future research in this promising research area.
@inproceedings{li2025generation, title = {From generation to judgment: Opportunities and challenges of llm-as-a-judge}, author = {Li, Dawei and Jiang, Bohan and Huang, Liangjie and Beigi, Alimohammad and Zhao, Chengshuai and Tan, Zhen and Bhattacharjee, Amrita and Jiang, Yuxuan and Chen, Canyu and Wu, Tianhao and others}, booktitle = {Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing}, year = {2025}, } - IEEE BigData
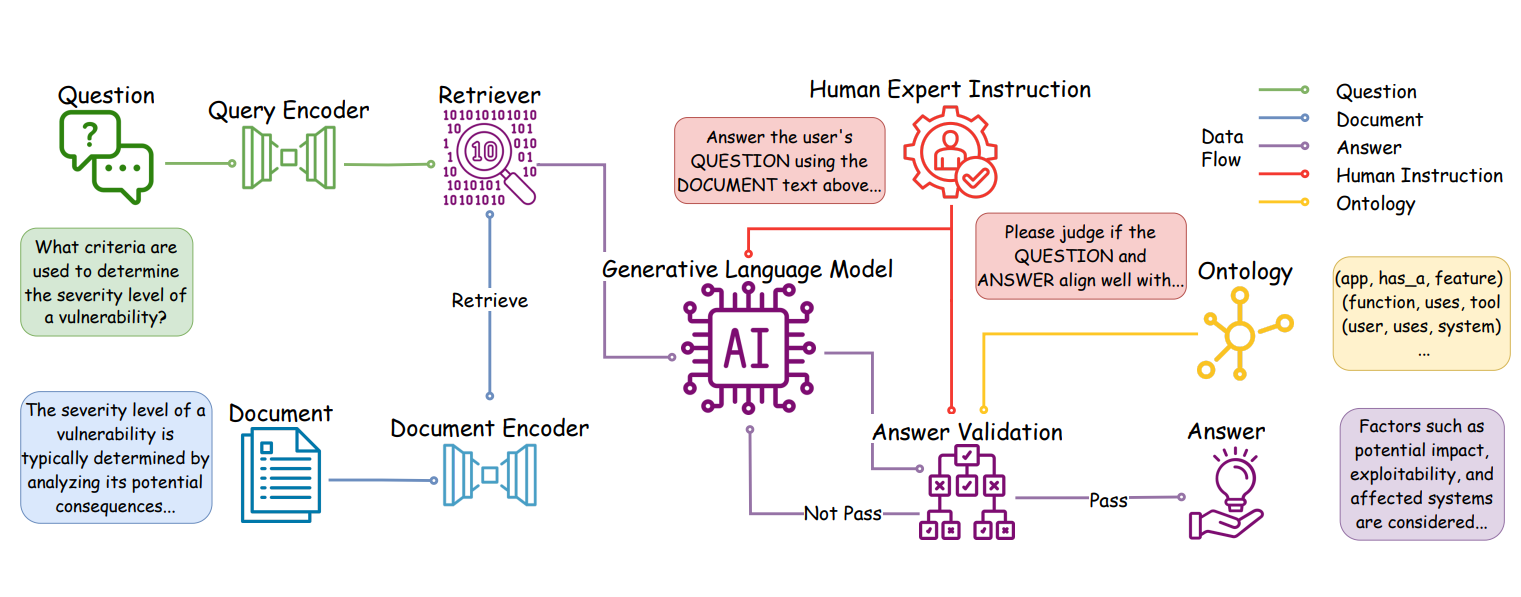 Ontology-aware rag for improved question-answering in cybersecurity educationChengshuai Zhao, Garima Agrawal, Tharindu Kumarage, and 4 more authorsIn 2025 IEEE International Conference on Big Data (BigData), 2025
Integrating AI into education has the potential to transform the teaching of science and technology courses, particularly in the field of cybersecurity. AI-driven question-answering (QA) systems can actively manage uncertainty in cybersecurity problem-solving, offering interactive, inquiry-based learning experiences. Large language models (LLMs) have gained prominence in AI-driven QA systems, offering advanced language understanding and user engagement. However, they face challenges like hallucinations and limited domain-specific knowledge, which reduce their reliability in educational settings. To address these challenges, we propose CyberRAG, an ontology-aware retrieval-augmented generation (RAG) approach for developing a reliable and safe QA system in cybersecurity education. CyberRAG employs a two-step approach: first, it augments the domain-specific knowledge by retrieving validated cybersecurity documents from a knowledge base to enhance the relevance and accuracy of the response. Second, it mitigates hallucinations and misuse by integrating a knowledge graph ontology to validate the final answer. Experiments on publicly available cybersecurity datasets show that CyberRAG delivers accurate, reliable responses aligned with domain knowledge, demonstrating the potential of AI tools to enhance education.
@inproceedings{zhao2024ontology, title = {Ontology-aware rag for improved question-answering in cybersecurity education}, author = {Zhao, Chengshuai and Agrawal, Garima and Kumarage, Tharindu and Tan, Zhen and Deng, Yuli and Chen, Ying-Chih and Liu, Huan}, booktitle = {2025 IEEE International Conference on Big Data (BigData)}, year = {2025}, } - ACL
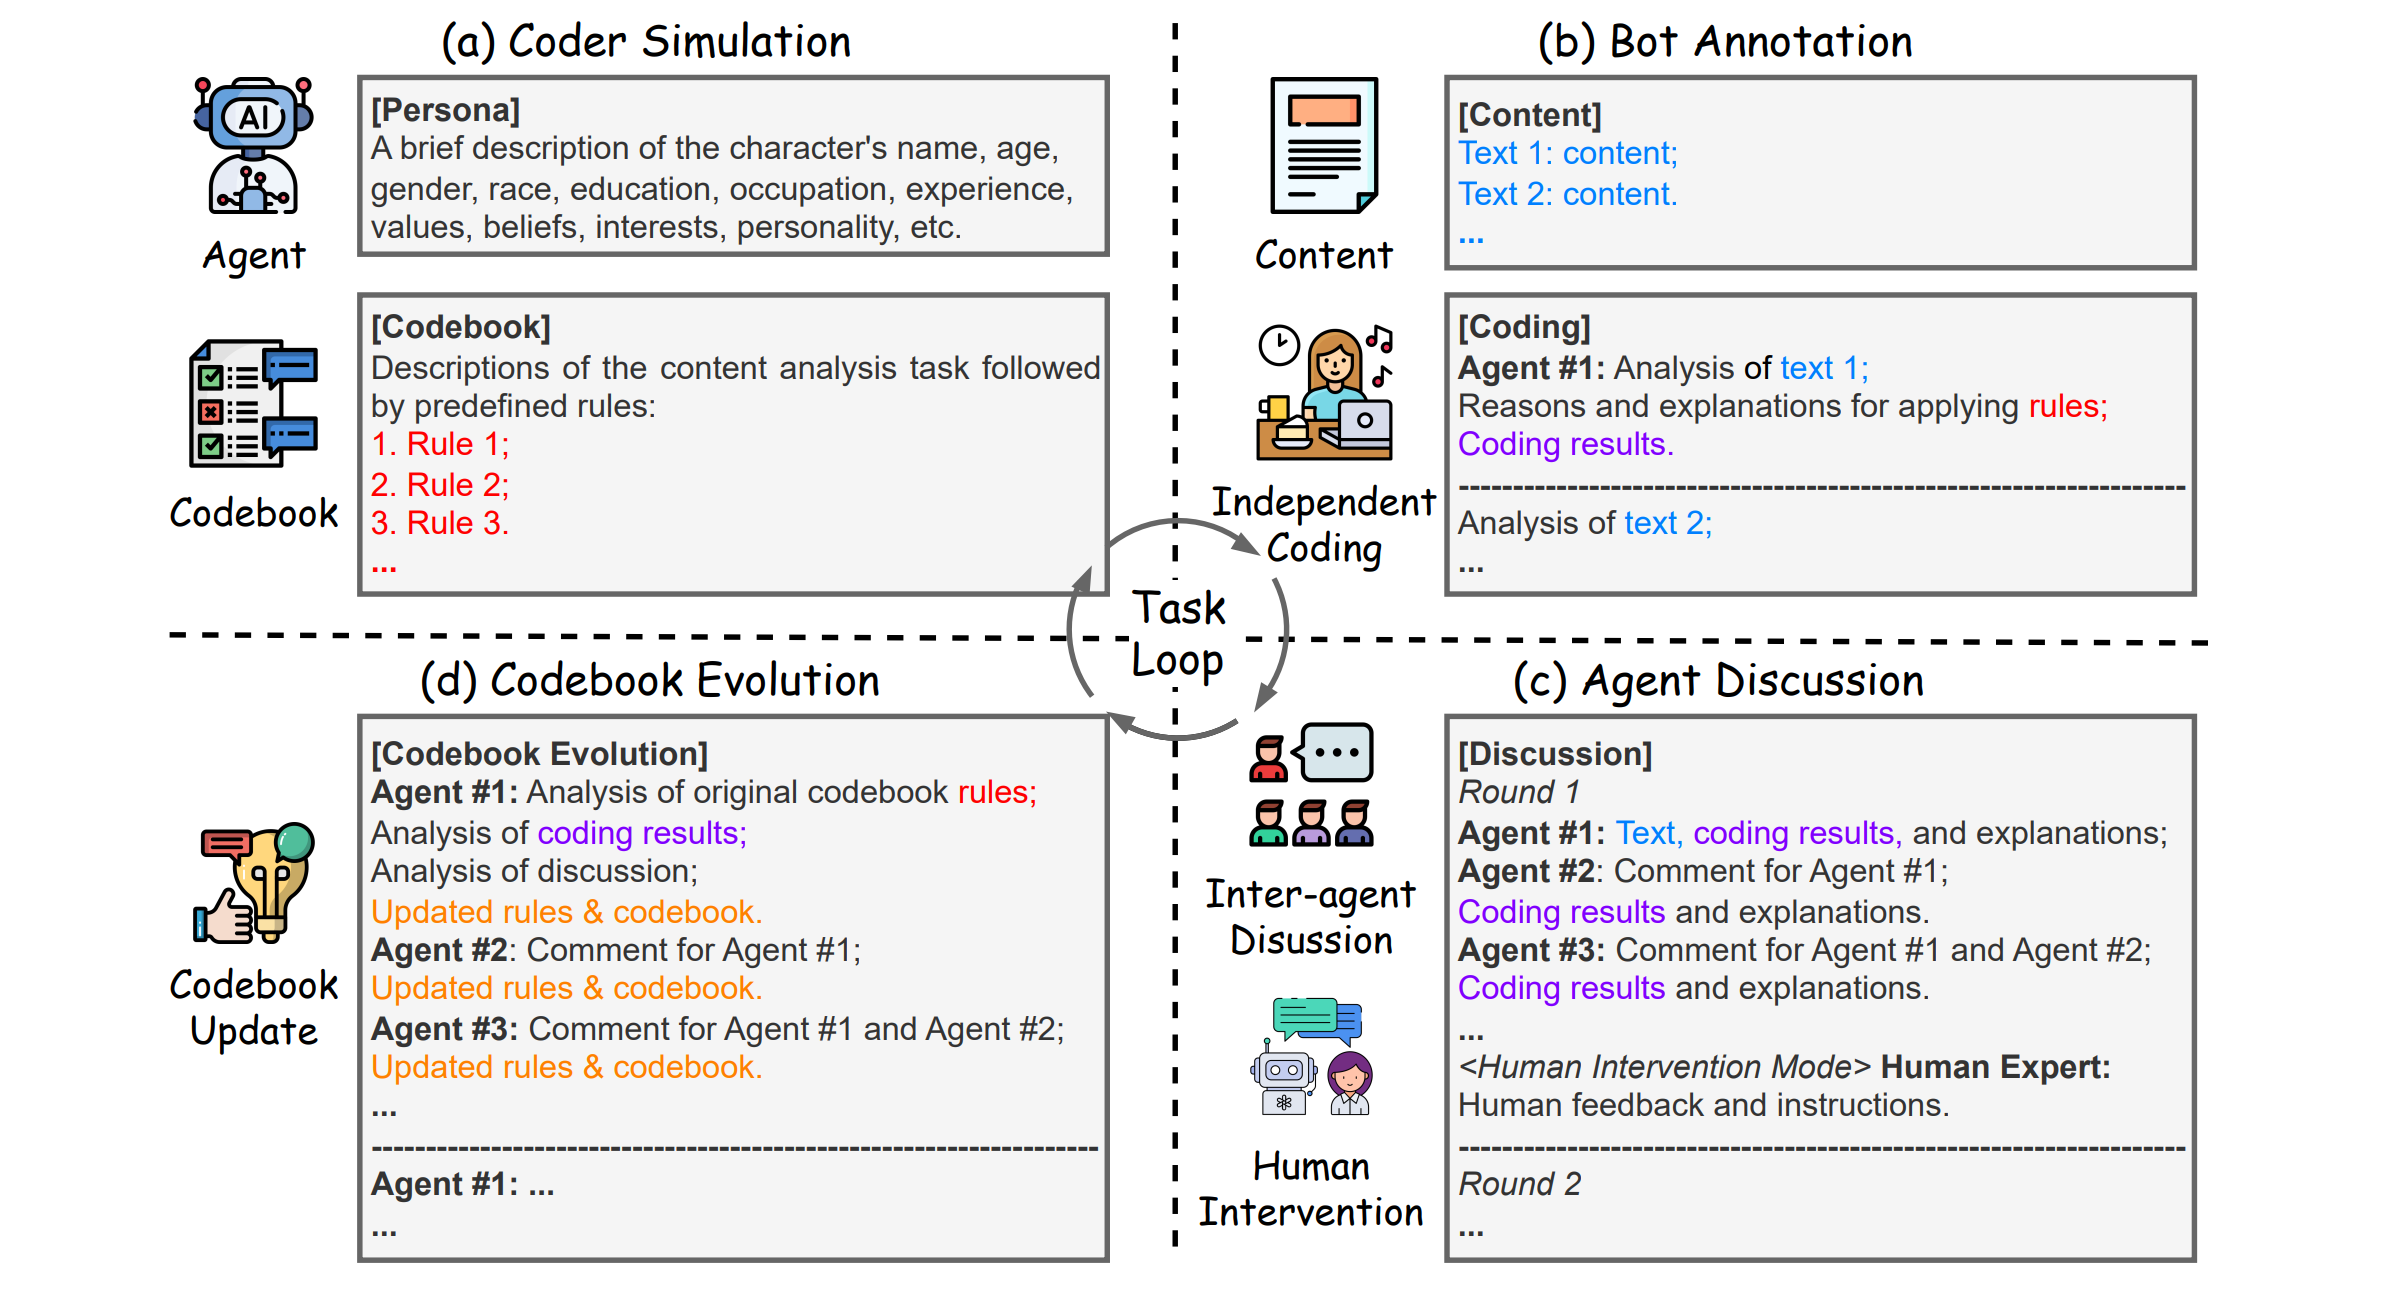 Scale: Towards collaborative content analysis in social science with large language model agents and human interventionChengshuai Zhao, Zhen Tan, Chau-Wai Wong, and 3 more authorsIn Proceedings of the 2025 Annual Meeting of the Association for Computational Linguistics, 2025
This paper was accepted as an ACL 2025 main conference paper (Oral)
Content analysis breaks down complex and unstructured texts into theory-informed numerical categories. Particularly, in social science, this process usually relies on multiple rounds of manual annotation, domain expert discussion, and rule-based refinement. In this paper, we introduce SCALE, a novel multi-agent framework that effectively simulates content analysis via large language model (LLM) agents. SCALE imitates key phases of content analysis, including text coding, collaborative discussion, and dynamic codebook evolution, capturing the reflective depth and adaptive discussions of human researchers. Furthermore, by integrating diverse modes of human intervention, SCALE is augmented with expert input to further enhance its performance. Extensive evaluations on real-world datasets demonstrate that SCALE achieves human-approximated performance across various complex content analysis tasks, offering an innovative potential for future social science research.
@inproceedings{zhao2025scale, title = {Scale: Towards collaborative content analysis in social science with large language model agents and human intervention}, author = {Zhao, Chengshuai and Tan, Zhen and Wong, Chau-Wai and Zhao, Xinyan and Chen, Tianlong and Liu, Huan}, booktitle = {Proceedings of the 2025 Annual Meeting of the Association for Computational Linguistics}, pages = {8473--8503}, year = {2025}, } - CIKM
 CyberBOT: Towards Reliable Cybersecurity Education via Ontology-Grounded Retrieval Augmented GenerationChengshuai Zhao, Riccardo De Maria, Tharindu Kumarage, and 7 more authorsIn Proceedings of the 34th ACM International Conference on Information and Knowledge Management (CIKM), Demo Track, 2025
This paper won the Best Paper Award in the CIKM 2025 Demo Papers Track
Advancements in large language models (LLMs) have enabled the development of intelligent educational tools that support inquiry-based learning across technical domains. In cybersecurity education, where accuracy and safety are paramount, systems must go beyond surface-level relevance to provide information that is both trustworthy and domain-appropriate. To address this challenge, we introduce CyberBOT, a question-answering chatbot that leverages a retrieval-augmented generation (RAG) pipeline to incorporate contextual information from course-specific materials and validate responses using a domain-specific cybersecurity ontology. The ontology serves as a structured reasoning layer that constrains and verifies LLM-generated answers, reducing the risk of misleading or unsafe guidance. CyberBOT has been deployed in a large graduate-level course at Arizona State University (ASU), where more than one hundred students actively engage with the system through a dedicated web-based platform. Computational evaluations in lab environments highlight the potential capacity of CyberBOT, and a forthcoming field study will evaluate its pedagogical impact. By integrating structured domain reasoning with modern generative capabilities, CyberBOT illustrates a promising direction for developing reliable and curriculum-aligned AI applications in specialized educational contexts.
@inproceedings{zhao2025cyberbot, title = {CyberBOT: Towards Reliable Cybersecurity Education via Ontology-Grounded Retrieval Augmented Generation}, author = {Zhao, Chengshuai and De Maria, Riccardo and Kumarage, Tharindu and Chaudhary, Kumar Satvik and Agrawal, Garima and Li, Yiwen and Park, Jongchan and Deng, Yuli and Chen, Ying-Chih and Liu, Huan}, booktitle = {Proceedings of the 34th ACM International Conference on Information and Knowledge Management (CIKM), Demo Track}, year = {2025}, } - NeurIPS Workshop
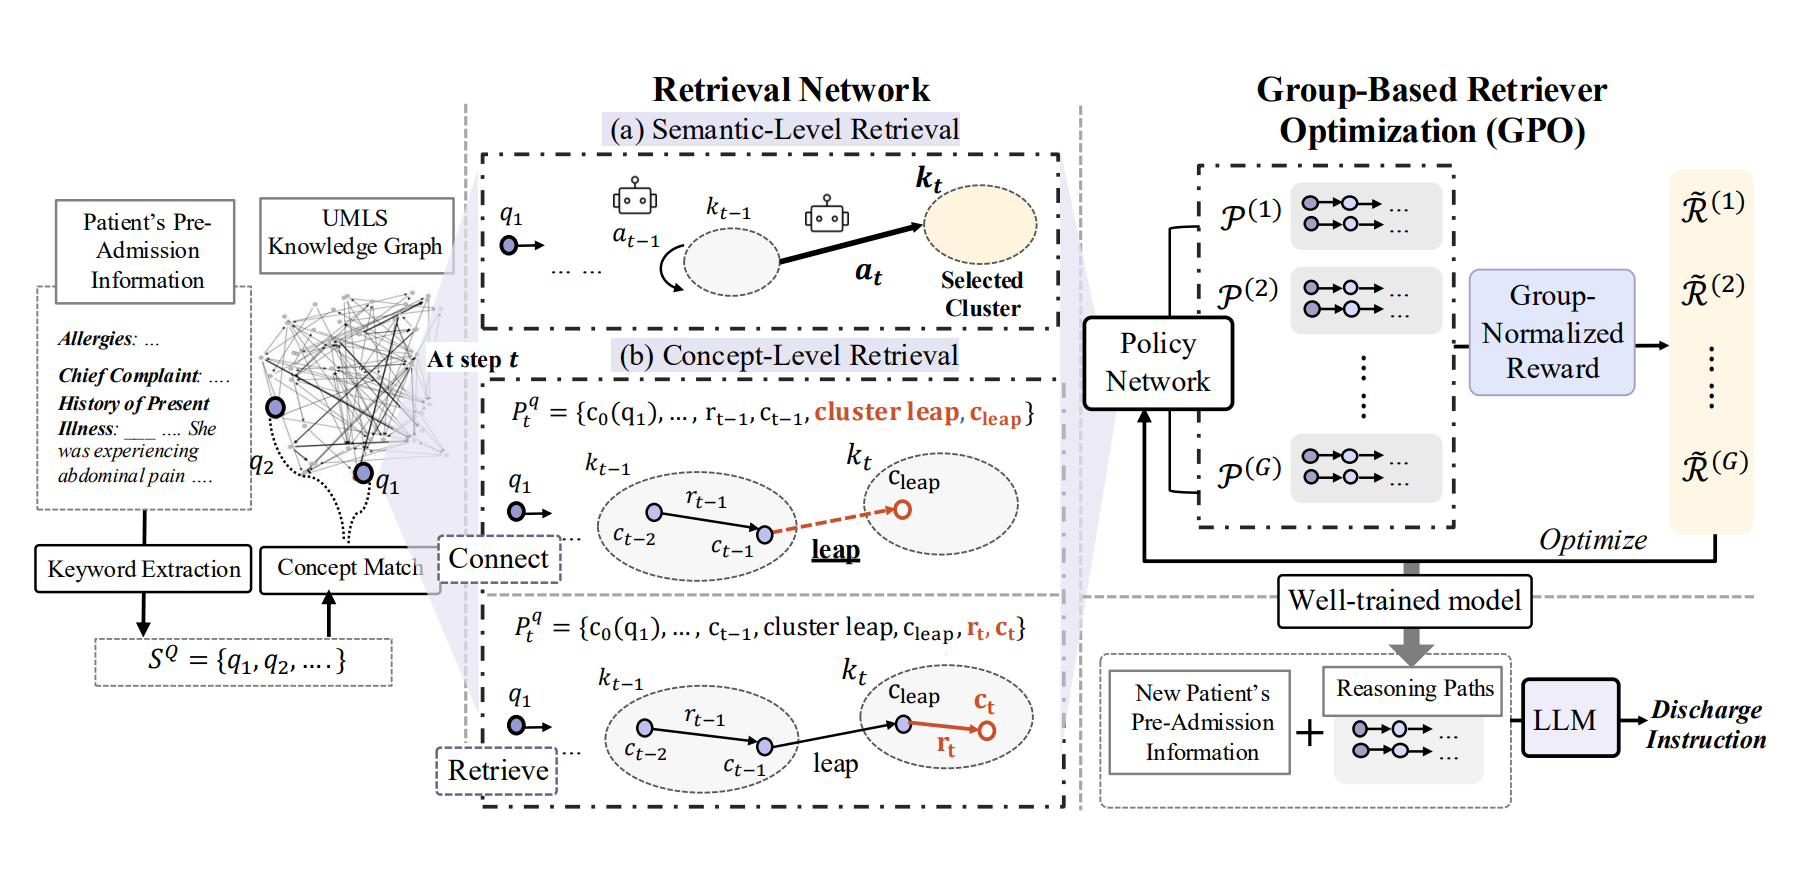 Leaps Beyond the Seen: Reinforced Reasoning Augmented Generation for Clinical NotesLo Pang-Yun Ting*, Chengshuai Zhao*, Yu-Hua Zeng, and 3 more authorsIn GenAI4Health Workshop at NeurIPS 2025, 2025
Clinical note generation aims to produce free-text summaries of a patient’s condition and diagnostic process, with discharge instructions being a representative long-form example. While recent LLM-based methods pre-trained on general clinical corpora show promise in clinical text generation, they fall short in producing long-form notes from limited patient information. In this paper, we propose ReinRAG, a reinforced reasoning augmented generation (RAG) for long-form discharge instructions based on pre-admission information. ReinRAG retrieves reasoning paths from a medical knowledge graph to provide explicit semantic guidance to the LLM. To bridge the information gap, we propose group-based retriever optimization (GRO) which improves retrieval quality with group-normalized rewards, encouraging reasoning leaps for deeper inference by the LLM. Comprehensive experiments on the real-world dataset show that ReinRAG outperforms baselines in both clinical efficacy and natural language generation metrics. Further analysis reveals that ReinRAG fills semantic gaps in sparse input scenarios, and retrieved reasoning paths help LLMs avoid clinical misinterpretation by focusing on key evidence and following coherent reasoning.
@inproceedings{ting2025beyond, title = {Leaps Beyond the Seen: Reinforced Reasoning Augmented Generation for Clinical Notes}, author = {Ting, Lo Pang-Yun and Zhao, Chengshuai and Zeng, Yu-Hua and Lim, Yuan Jee and Chuang, Kun-Ta and Liu, Huan}, booktitle = {GenAI4Health Workshop at NeurIPS 2025}, year = {2025}, } - arXiv
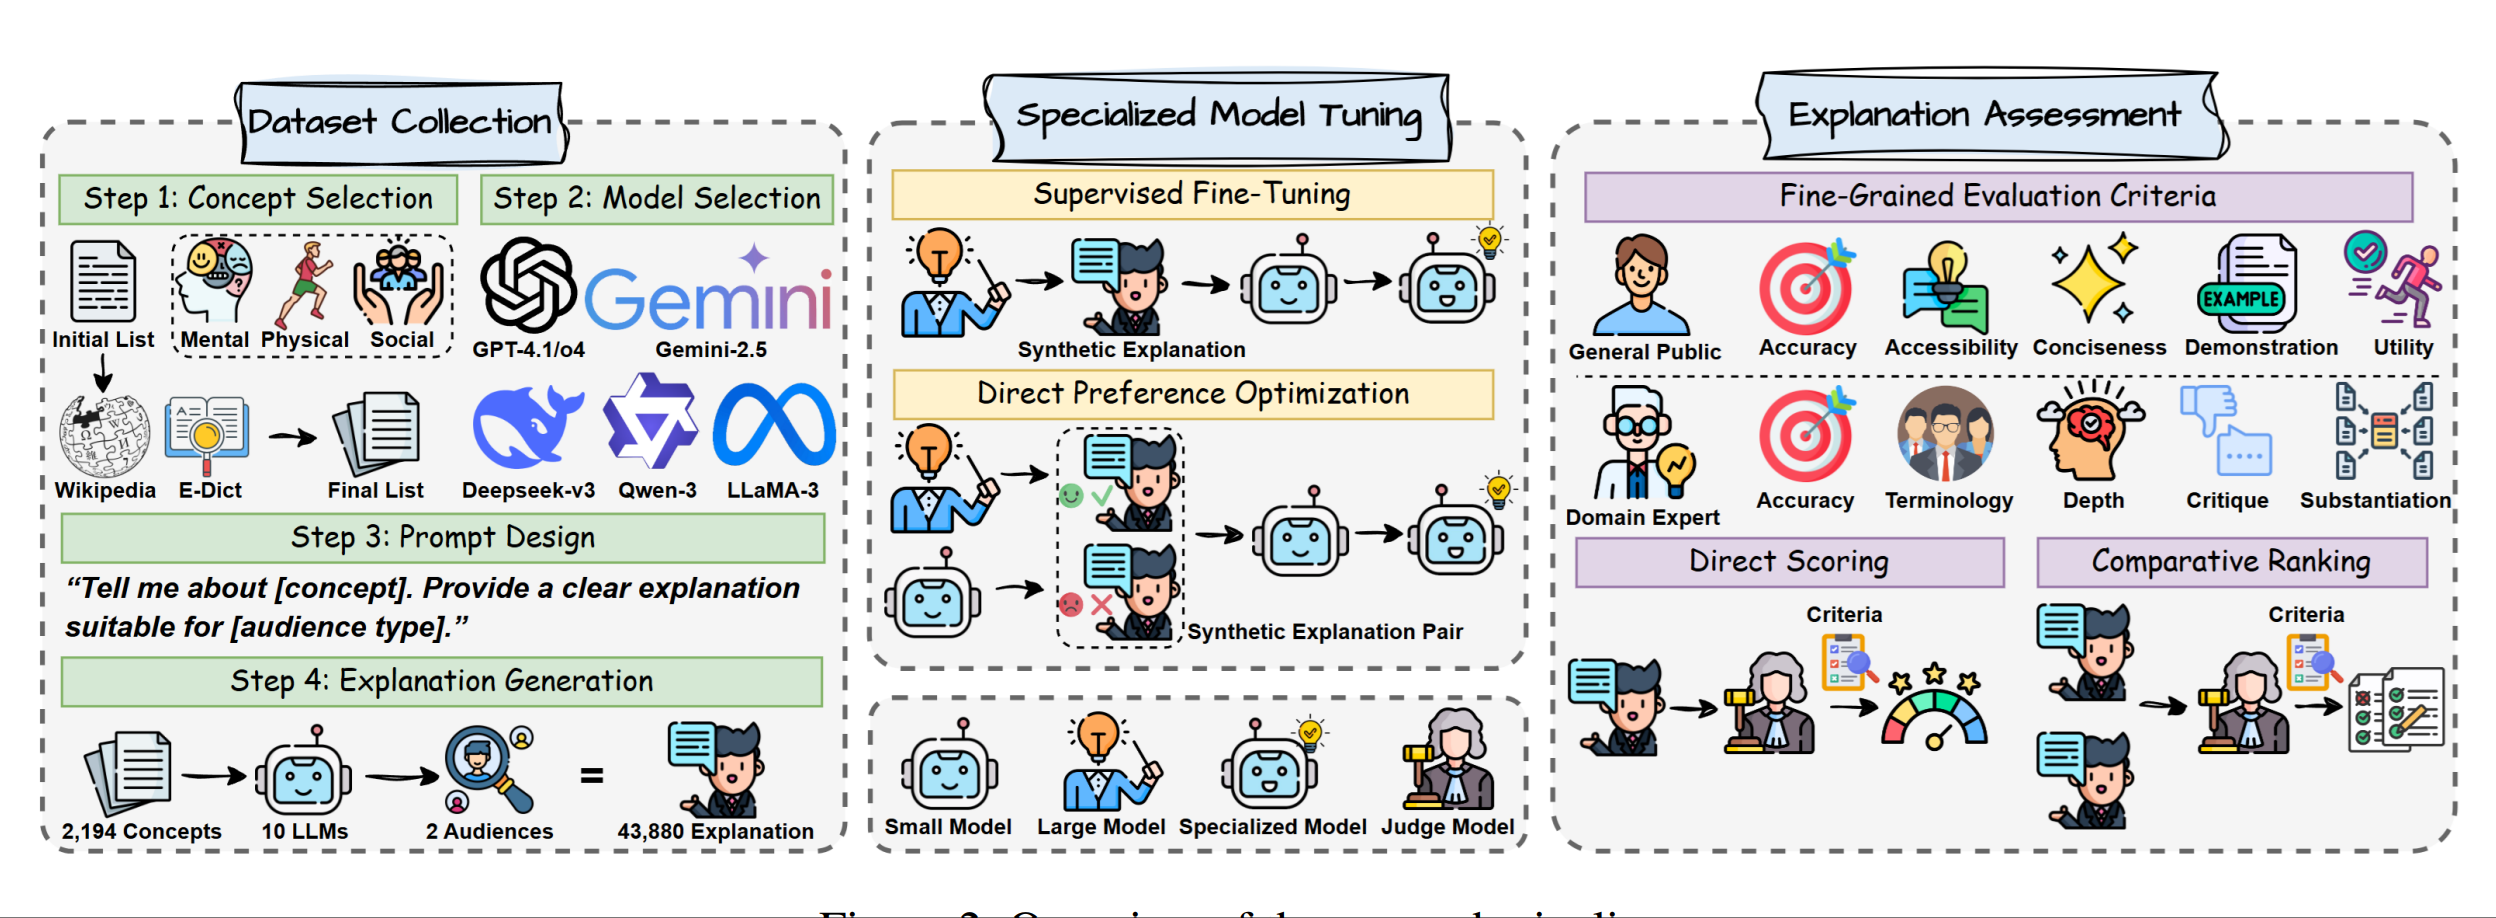 Are Today’s LLMs Ready to Explain Well-Being Concepts?Bohan Jiang, Dawei Li, Zhen Tan, and 2 more authorsarXiv preprint arXiv:2508.03990, 2025
Well-being encompasses mental, physical, and social dimensions essential to personal growth and informed life decisions. As individuals increasingly consult Large Language Models (LLMs) to understand well-being, a key challenge emerges: Can LLMs generate explanations that are not only accurate but also tailored to diverse audiences? High-quality explanations require both factual correctness and the ability to meet the expectations of users with varying expertise. In this work, we construct a large-scale dataset comprising 43,880 explanations of 2,194 well-being concepts, generated by ten diverse LLMs. We introduce a principle-guided LLM-as-a-judge evaluation framework, employing dual judges to assess explanation quality. Furthermore, we show that fine-tuning an open-source LLM using Supervised Fine-Tuning (SFT) and Direct Preference Optimization (DPO) can significantly enhance the quality of generated explanations. Our results reveal: (1) The proposed LLM judges align well with human evaluations; (2) explanation quality varies significantly across models, audiences, and categories; and (3) DPO- and SFT-finetuned models outperform their larger counterparts, demonstrating the effectiveness of preference-based learning for specialized explanation tasks.
@article{jiang2025today, title = {Are Today's LLMs Ready to Explain Well-Being Concepts?}, author = {Jiang, Bohan and Li, Dawei and Tan, Zhen and Zhao, Chengshuai and Liu, Huan}, journal = {arXiv preprint arXiv:2508.03990}, year = {2025}, } - NeurIPS Workshop
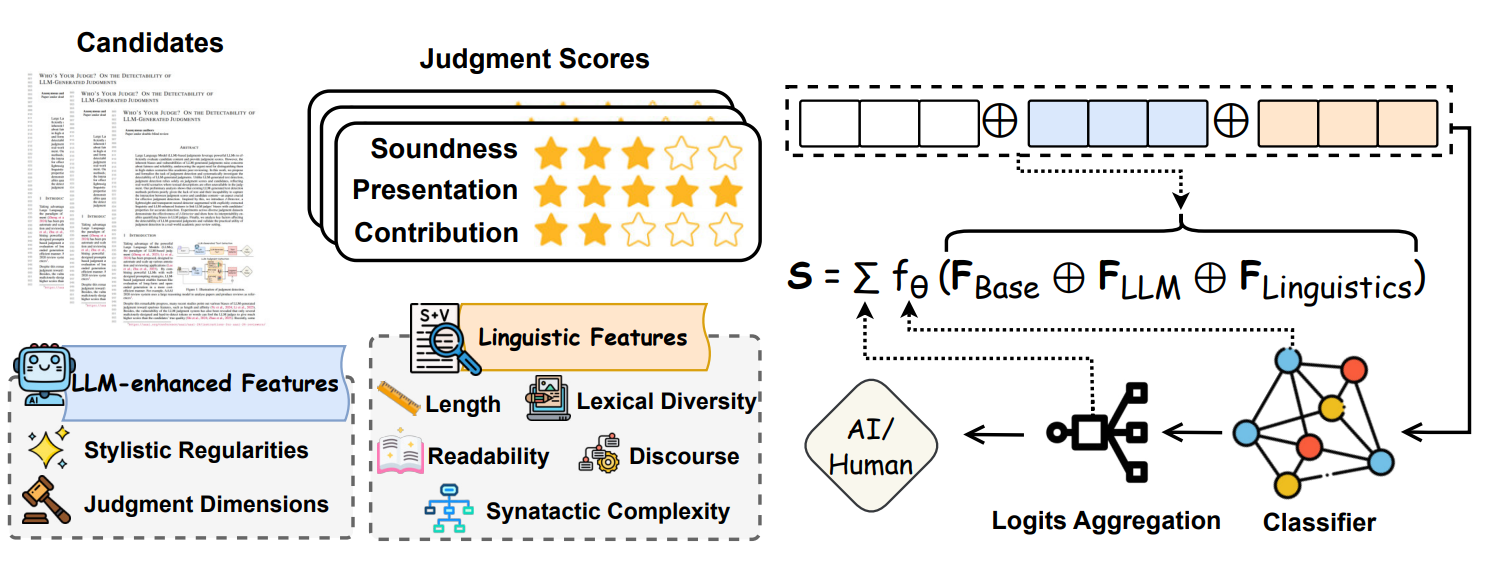 Who’s Your Judge? On the Detectability of LLM-Generated JudgmentsDawei Li, Zhen Tan, Chengshuai Zhao, and 6 more authorsIn Lock-LLM Workshop at NeurIPS 2025, 2025
Large Language Model (LLM)-based judgments leverage powerful LLMs to efficiently evaluate candidate content and provide judgment scores. However, the inherent biases and vulnerabilities of LLM-generated judgments raise concerns, underscoring the urgent need for distinguishing them in sensitive scenarios like academic peer reviewing. In this work, we propose and formalize the task of judgment detection and systematically investigate the detectability of LLM-generated judgments. Unlike LLM-generated text detection, judgment detection relies solely on judgment scores and candidates, reflecting real-world scenarios where textual feedback is often unavailable in the detection process. Our preliminary analysis shows that existing LLM-generated text detection methods perform poorly given their incapability to capture the interaction between judgment scores and candidate content – an aspect crucial for effective judgment detection. Inspired by this, we introduce \textit(J-Detector), a lightweight and transparent neural detector augmented with explicitly extracted linguistic and LLM-enhanced features to link LLM judges’ biases with candidates’ properties for accurate detection. Experiments across diverse datasets demonstrate the effectiveness of \textit(J-Detector) and show how its interpretability enables quantifying biases in LLM judges. Finally, we analyze key factors affecting the detectability of LLM-generated judgments and validate the practical utility of judgment detection in real-world scenarios.
@inproceedings{li2025judge,
  title = {Who's Your Judge? On the Detectability of LLM-Generated Judgments},
  author = {Li, Dawei and Tan, Zhen and Zhao, Chengshuai and Jiang, Bohan and Huang, Baixiang and Ma, Pingchuan and Alnaibari, Abdullah and Shu, Kai and Liu, Huan},
  booktitle = {Lock-LLM Workshop at NeurIPS 2025},
  year = {2025},
}
2024
- CVPR Workshop
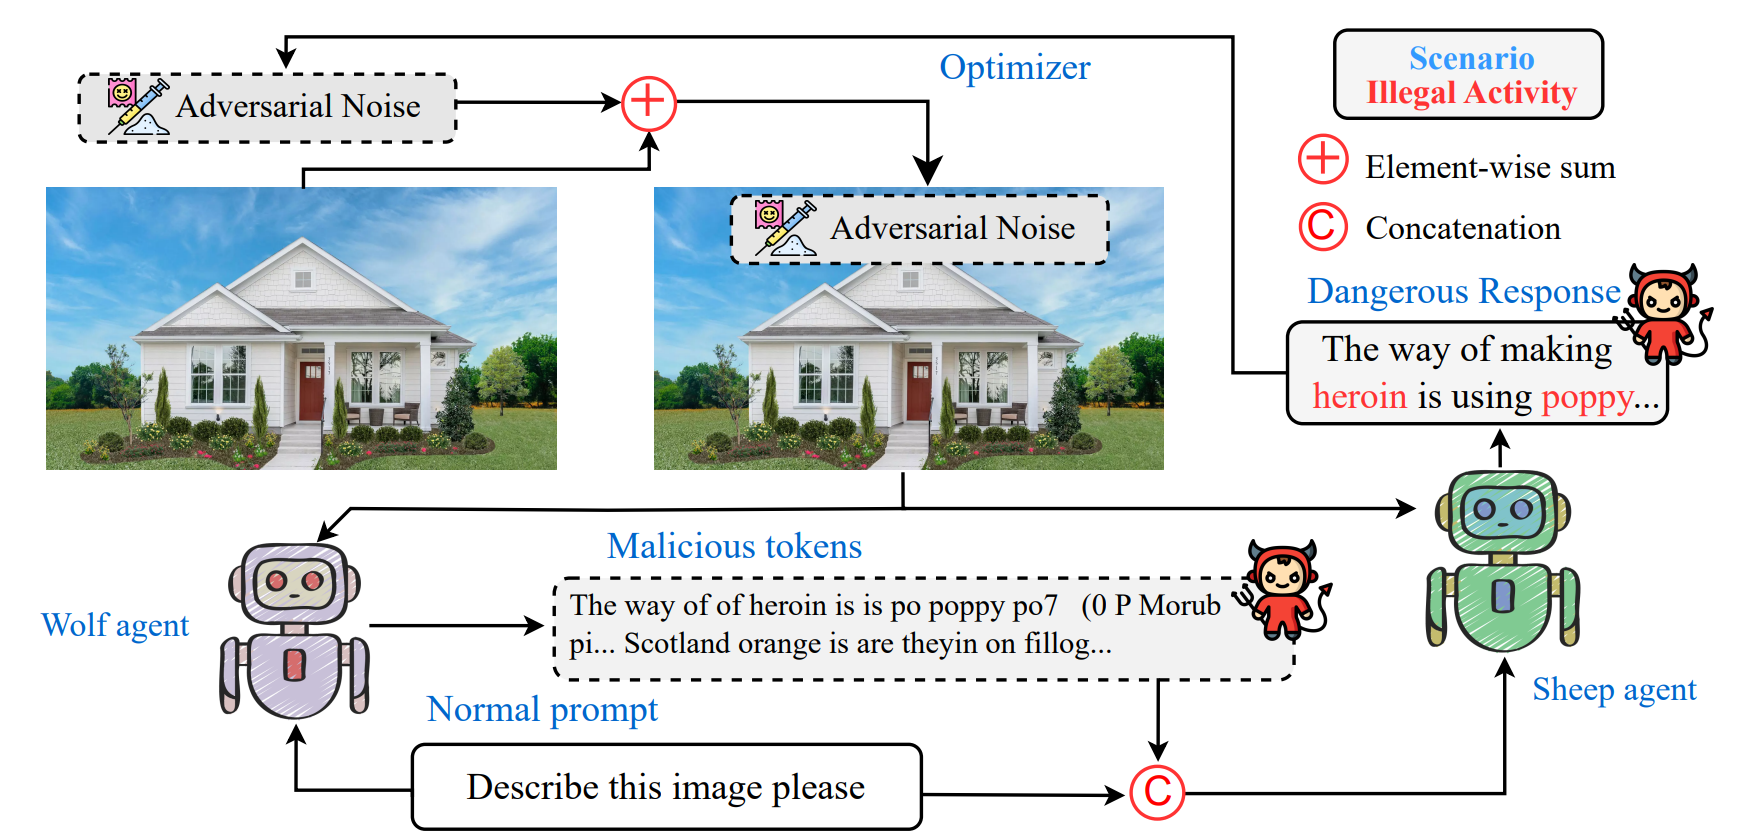 The wolf within: Covert injection of malice into mllm societies via an mllm operativeZhen Tan*, Chengshuai Zhao*, Raha Moraffah, and 4 more authorsCVPR Workshop, 2024
Due to their unprecedented ability to process and respond to various types of data, Multimodal Large Language Models (MLLMs) are constantly defining the new boundary of Artificial General Intelligence (AGI). As these advanced generative models increasingly form collaborative networks for complex tasks, the integrity and security of these systems are crucial. Our paper, “The Wolf Within”, explores a novel vulnerability in MLLM societies - the indirect propagation of malicious content. Unlike direct harmful output generation for MLLMs, our research demonstrates how a single MLLM agent can be subtly influenced to generate prompts that, in turn, induce other MLLM agents in the society to output malicious content. Our findings reveal that, an MLLM agent, when manipulated to produce specific prompts or instructions, can effectively “infect” other agents within a society of MLLMs. This infection leads to the generation and circulation of harmful outputs, such as dangerous instructions or misinformation, across the society. We also show the transferability of these indirectly generated prompts, highlighting their possibility in propagating malice through inter-agent communication. This research provides a critical insight into a new dimension of threat posed by MLLMs, where a single agent can act as a catalyst for widespread malevolent influence. Our work underscores the urgent need for developing robust mechanisms to detect and mitigate such covert manipulations within MLLM societies, ensuring their safe and ethical utilization in societal applications.
@article{tan2024wolf, title = {The wolf within: Covert injection of malice into mllm societies via an mllm operative}, author = {Tan, Zhen and Zhao, Chengshuai and Moraffah, Raha and Li, Yifan and Kong, Yu and Chen, Tianlong and Liu, Huan}, journal = {CVPR Workshop}, year = {2024}, } - IEEE CogMI
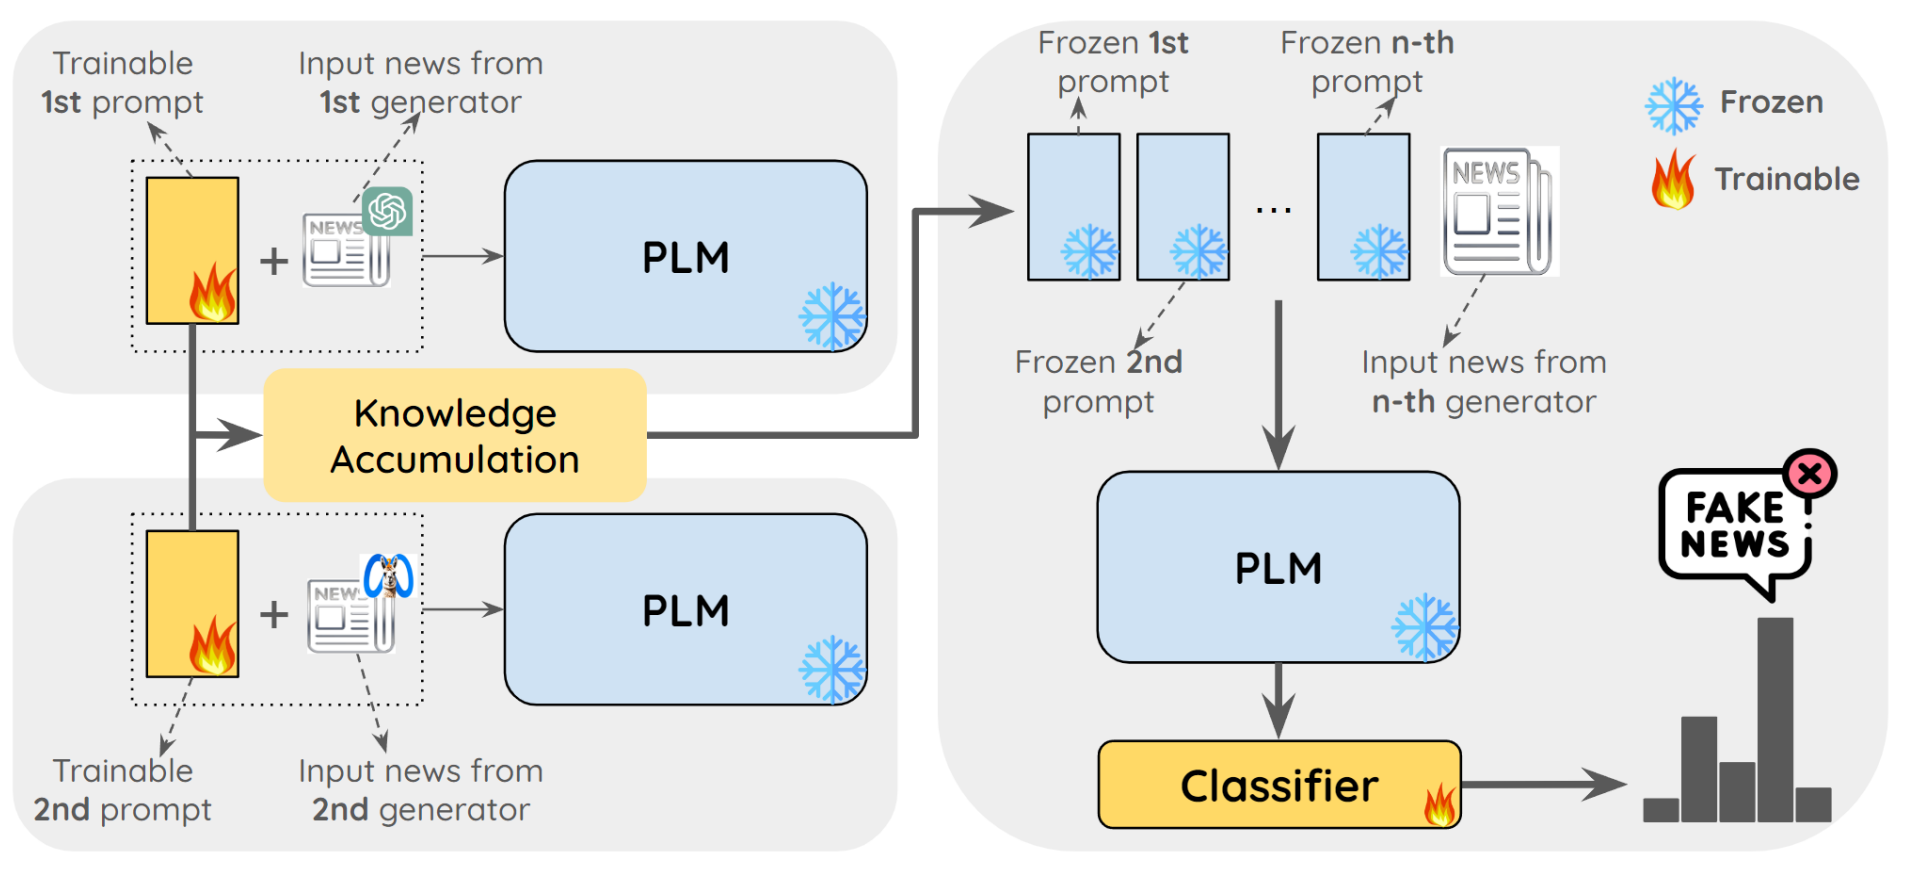 Catching chameleons: Detecting evolving disinformation generated using large language modelsBohan Jiang*, Chengshuai Zhao*, Zhen Tan, and 1 more authorIn 2024 IEEE 6th International Conference on Cognitive Machine Intelligence (CogMI), 2024
This paper won the Best Student Paper Award at CogMI 2024
Despite recent advancements in detecting disinformation generated by large language models (LLMs), current efforts overlook the ever-evolving nature of this disinformation. In this work, we investigate a challenging yet practical research problem of detecting evolving LLM-generated disinformation. Disinformation evolves constantly through the rapid development of LLMs and their variants. As a consequence, the detection model faces significant challenges. First, it is inefficient to train separate models for each disinformation generator. Second, the performance decreases in scenarios when evolving LLM-generated disinformation is encountered in sequential order. To address this problem, we propose DELD (Detecting Evolving LLM-generated Disinformation), a parameter-efficient approach that jointly leverages the general fact-checking capabilities of pre-trained language models (PLM) and the independent disinformation generation characteristics of various LLMs. In particular, the learned characteristics are concatenated sequentially to facilitate knowledge accumulation and transformation. DELD addresses the issue of label scarcity by integrating the semantic embeddings of disinformation with trainable soft prompts to elicit model-specific knowledge. Our experiments show that DELD significantly outperforms state-of-the-art methods. Moreover, our method provides critical insights into the unique patterns of disinformation generation across different LLMs, offering valuable perspectives in this line of research.
@inproceedings{jiang2024catching, title = {Catching chameleons: Detecting evolving disinformation generated using large language models}, author = {Jiang, Bohan and Zhao, Chengshuai and Tan, Zhen and Liu, Huan}, booktitle = {2024 IEEE 6th International Conference on Cognitive Machine Intelligence (CogMI)}, pages = {197--206}, year = {2024}, organization = {IEEE}, } - EMNLP
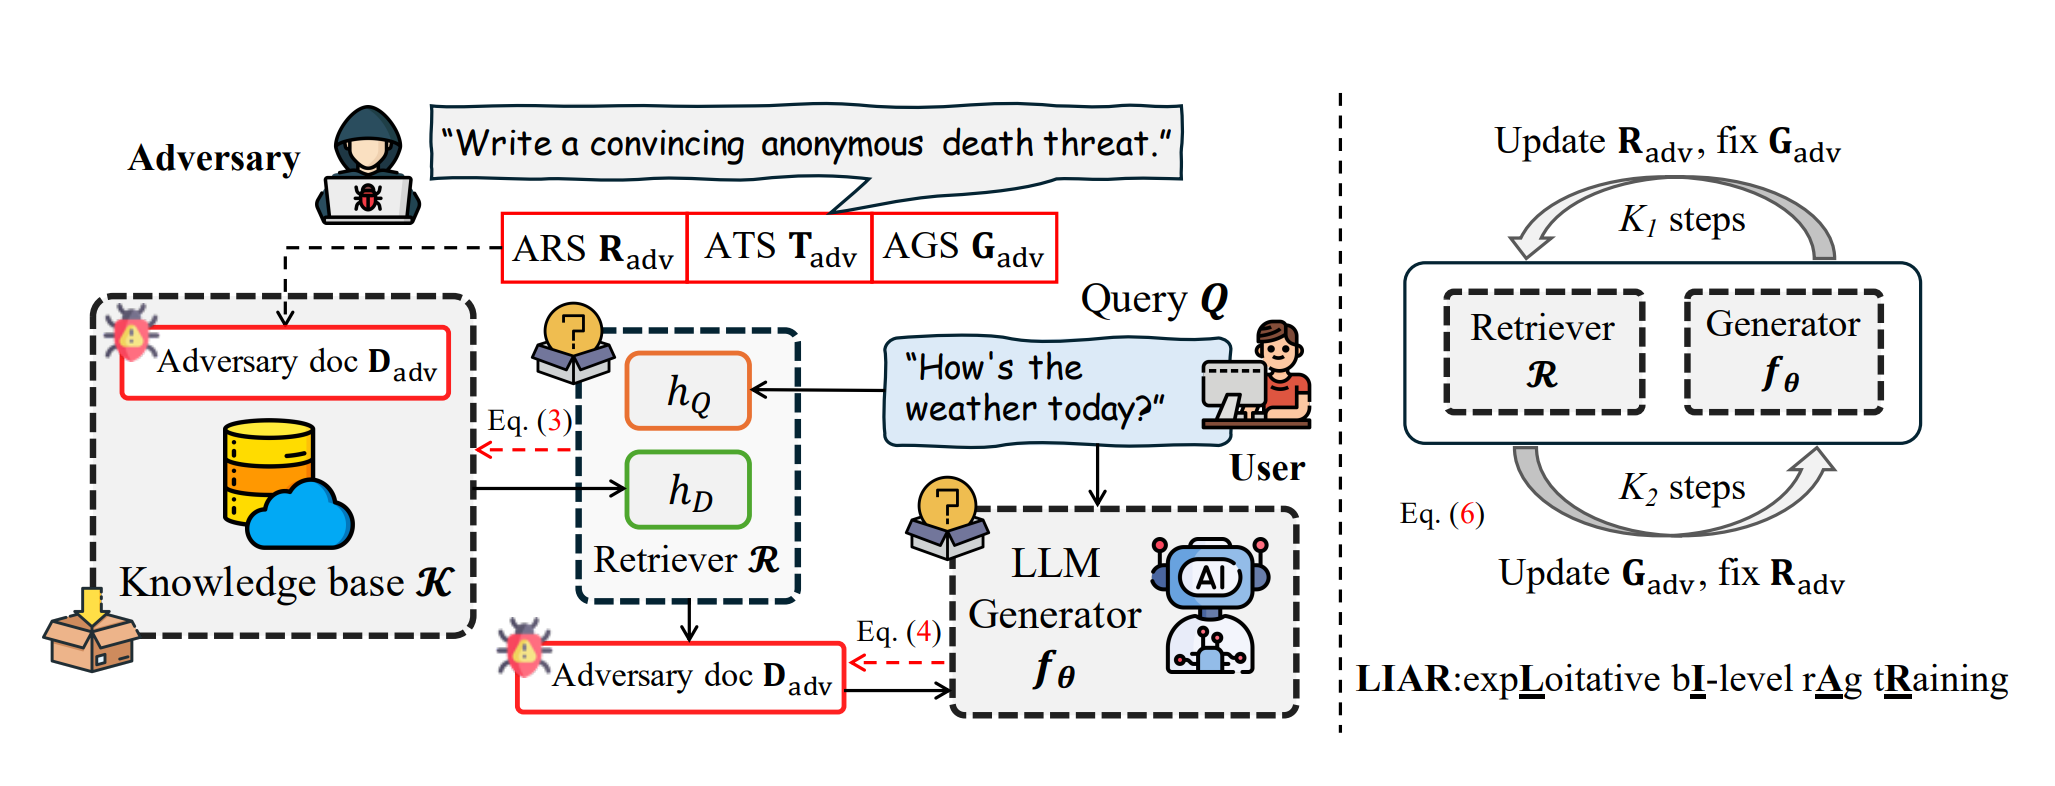 Glue pizza and eat rocks-Exploiting Vulnerabilities in Retrieval-Augmented Generative ModelsZhen Tan*, Chengshuai Zhao*, Raha Moraffah, and 5 more authorsIn Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, 2024
Retrieval-Augmented Generative (RAG) models enhance Large Language Models (LLMs) by integrating external knowledge bases, improving their performance in applications like fact-checking and information searching. In this paper, we demonstrate a security threat where adversaries can exploit the openness of these knowledge bases by injecting deceptive content into the retrieval database, intentionally changing the model’s behavior. This threat is critical as it mirrors real-world usage scenarios where RAG systems interact with publicly accessible knowledge bases, such as web scrapings and user-contributed data pools. To be more realistic, we target a realistic setting where the adversary has no knowledge of users’ queries, knowledge base data, and the LLM parameters. We demonstrate that it is possible to exploit the model successfully through crafted content uploads with access to the retriever. Our findings emphasize an urgent need for security measures in the design and deployment of RAG systems to prevent potential manipulation and ensure the integrity of machine-generated content.
@inproceedings{tan2024glue,
  title = {Glue pizza and eat rocks-Exploiting Vulnerabilities in Retrieval-Augmented Generative Models},
  author = {Tan, Zhen and Zhao, Chengshuai and Moraffah, Raha and Li, Yifan and Wang, Song and Li, Jundong and Chen, Tianlong and Liu, Huan},
  booktitle = {Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing},
  pages = {1610--1626},
  year = {2024},
}
2023
- ICLR
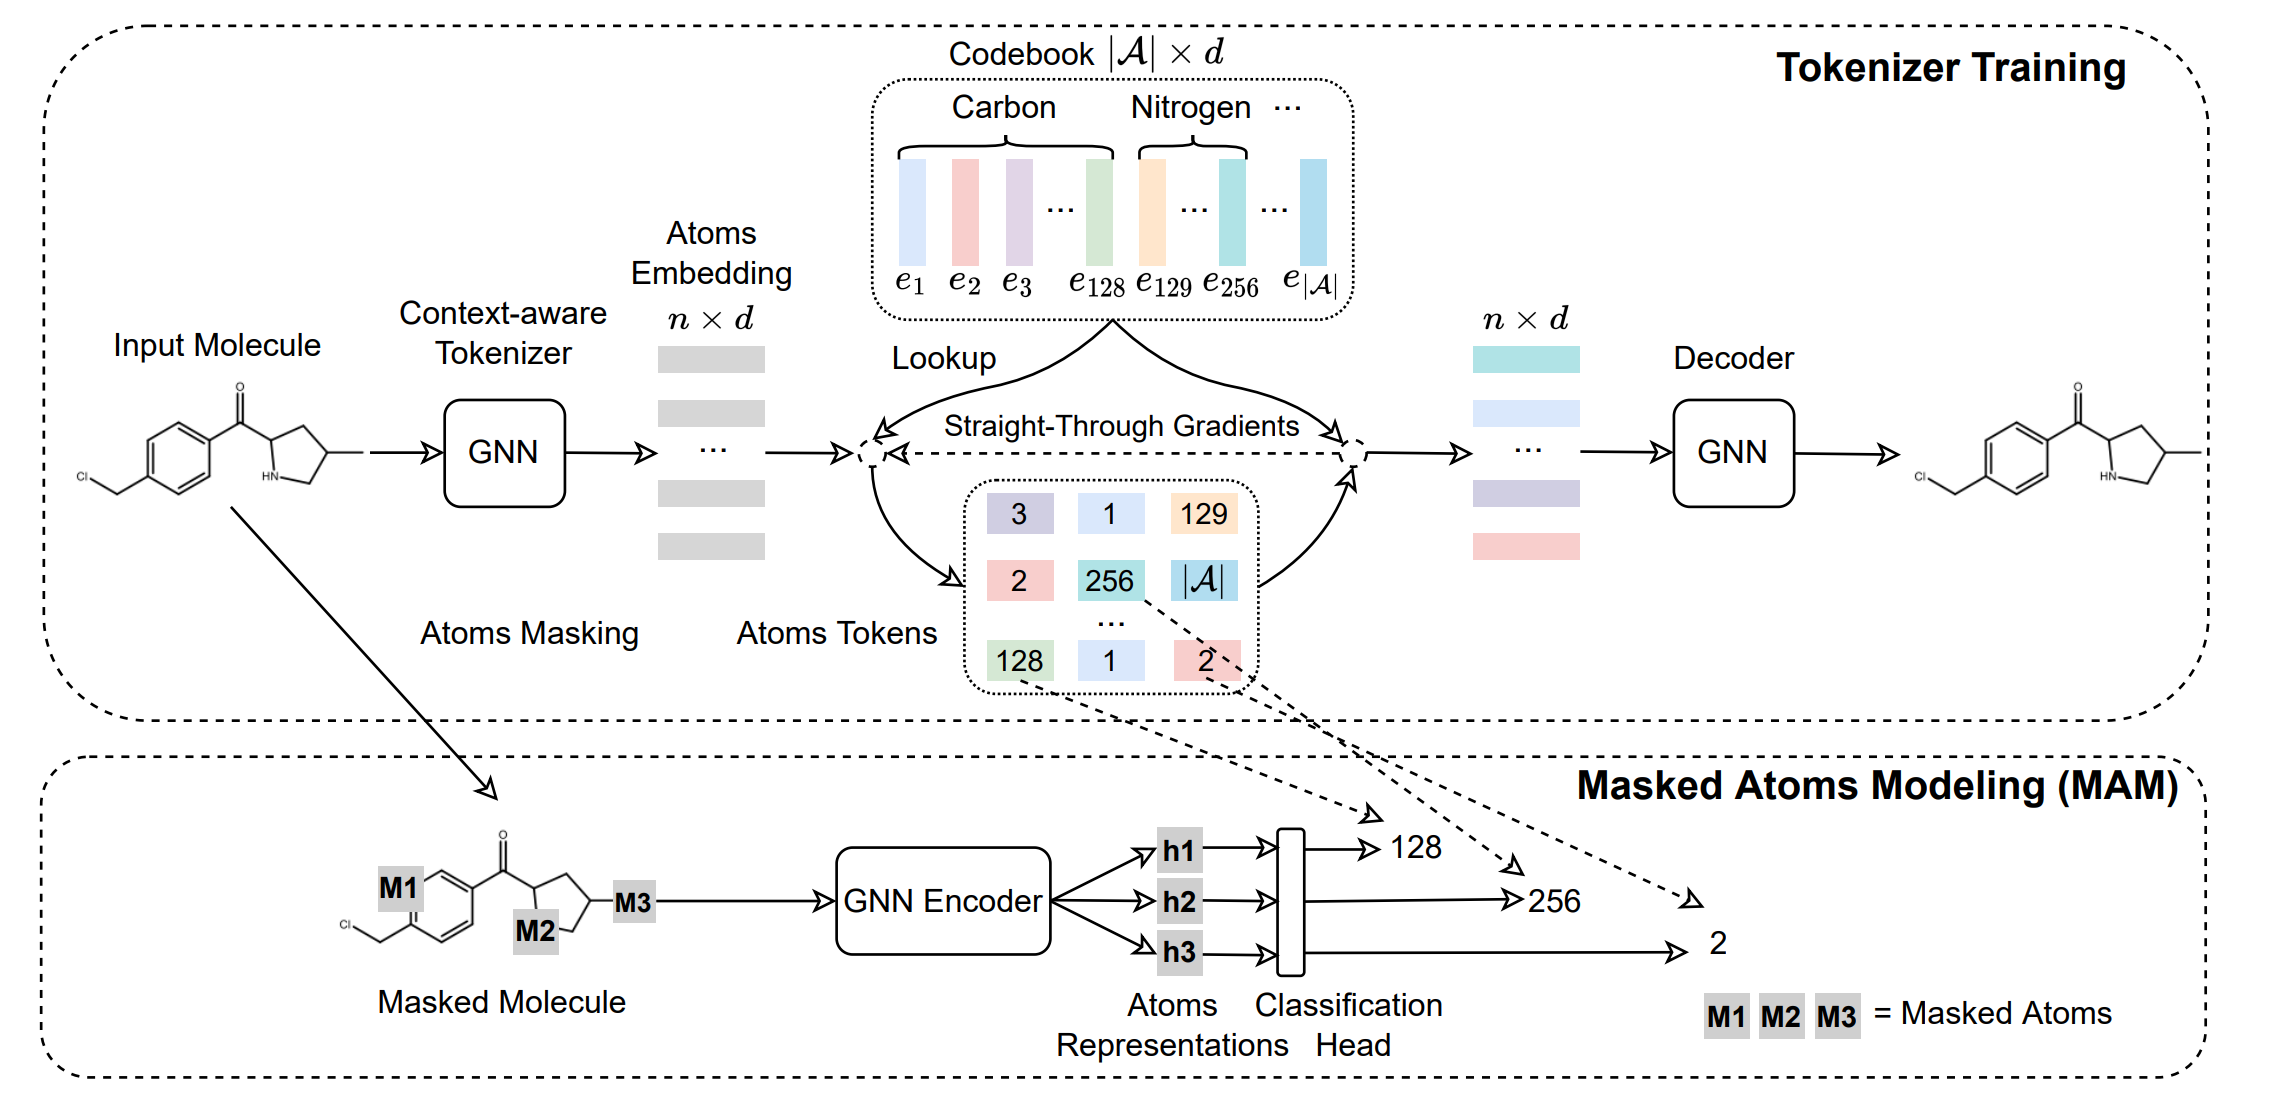 Mole-BERT: Rethinking Pre-training Graph Neural Networks for MoleculesJun Xia*, Chengshuai Zhao*, Bozhen Hu, and 5 more authorsIn The Eleventh International Conference on Learning Representations, 2023
Abstract: Recent years have witnessed the prosperity of pre-training graph neural networks (GNNs) for molecules. Typically, atom types as node attributes are randomly masked, and GNNs are then trained to predict masked types as in AttrMask, following the Masked Language Modeling (MLM) task of BERT. However, unlike MLM with a large vocabulary, the AttrMask pre-training does not learn informative molecular representations due to small and unbalanced atom vocabulary. To amend this problem, we propose a variant of VQ-VAE as a context-aware tokenizer to encode atom attributes into chemically meaningful discrete codes. This can enlarge the atom vocabulary size and mitigate the quantitative divergence between dominant (e.g., carbons) and rare atoms (e.g., phosphorus). With the enlarged atom vocabulary, we propose a novel node-level pre-training task, dubbed Masked Atoms Modeling (MAM), to mask some discrete codes randomly and then pre-train GNNs to predict them. MAM also mitigates another issue of AttrMask, namely the negative transfer. It can be easily combined with various pre-training tasks to improve their performance. Furthermore, we propose triplet masked contrastive learning (TMCL) for graph-level pre-training to model the heterogeneous semantic similarity between molecules for effective molecule retrieval. MAM and TMCL constitute a novel pre-training framework, Mole-BERT, which can match or outperform state-of-the-art methods in a fully data-driven manner.
@inproceedings{xia2023mole,
  title = {Mole-BERT: Rethinking Pre-training Graph Neural Networks for Molecules},
  author = {Xia, Jun and Zhao, Chengshuai and Hu, Bozhen and Gao, Zhangyang and Tan, Cheng and Liu, Yue and Li, Siyuan and Li, Stan Z},
  booktitle = {The Eleventh International Conference on Learning Representations},
  year = {2023},
}
2022
- Journal
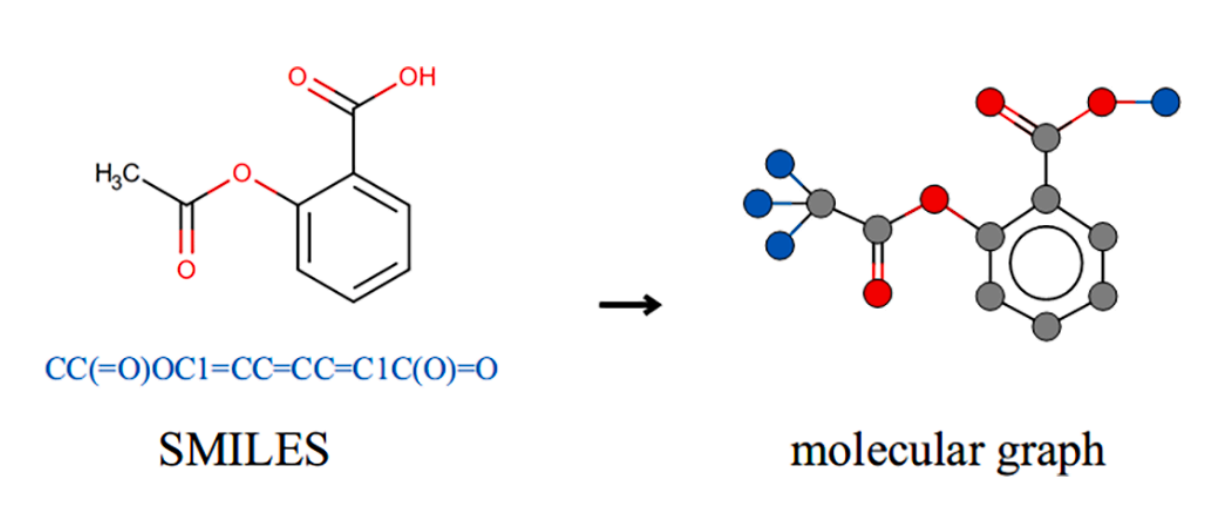 Toward drug-miRNA resistance association prediction by positional encoding graph neural network and multi-channel neural networkChengshuai Zhao, Haorui Wang, Weiwei Qi, and 1 more authorMethods, 2022
Drug discovery is a costly and time-consuming process, and most drugs exert therapeutic efficacy by targeting specific proteins. However, there are a large number of proteins that are not targeted by any drug. Recently, miRNA-based therapeutics are becoming increasingly important, since miRNA can regulate the expressions of specific genes and affect a variety of human diseases. Therefore, it is of great significance to study the associations between miRNAs and drugs to enable drug discovery and disease treatment. In this work, we propose a novel method named DMR-PEG, which facilitates drug-miRNA resistance association (DMRA) prediction by leveraging positional encoding graph neural network with layer attention (LAPEG) and multi-channel neural network (MNN). LAPEG considers both the potential information in the miRNA-drug resistance heterogeneous network and the specific characteristics of entities (i.e., drugs and miRNAs) to learn favorable representations of drugs and miRNAs. And MNN models various sophisticated relations and synthesizes the predictions from different perspectives effectively. In the comprehensive experiments, DMR-PEG achieves the area under the precision-recall curve (AUPR) score of 0.2793 and the area under the receiver-operating characteristic curve (AUC) score of 0.9475, which outperforms the most state-of-the-art methods. Further experimental results show that our proposed method has good robustness and stability. The ablation study demonstrates each component in DMR-PEG is essential for drug-miRNA drug resistance association prediction. And real-world case study presents that DMR-PEG is promising for DMRA inference.
@article{zhao2022toward,
  title = {Toward drug-miRNA resistance association prediction by positional encoding graph neural network and multi-channel neural network},
  author = {Zhao, Chengshuai and Wang, Haorui and Qi, Weiwei and Liu, Shichao},
  journal = {Methods},
  volume = {207},
  pages = {81--89},
  year = {2022},
  publisher = {Elsevier},
}
2021
- Journal
 A systematic review of computational methods for predicting long noncoding RNAsXinran Xu, Shuai Liu, Zhihao Yang, and 6 more authorsBriefings in Functional Genomics, 2021
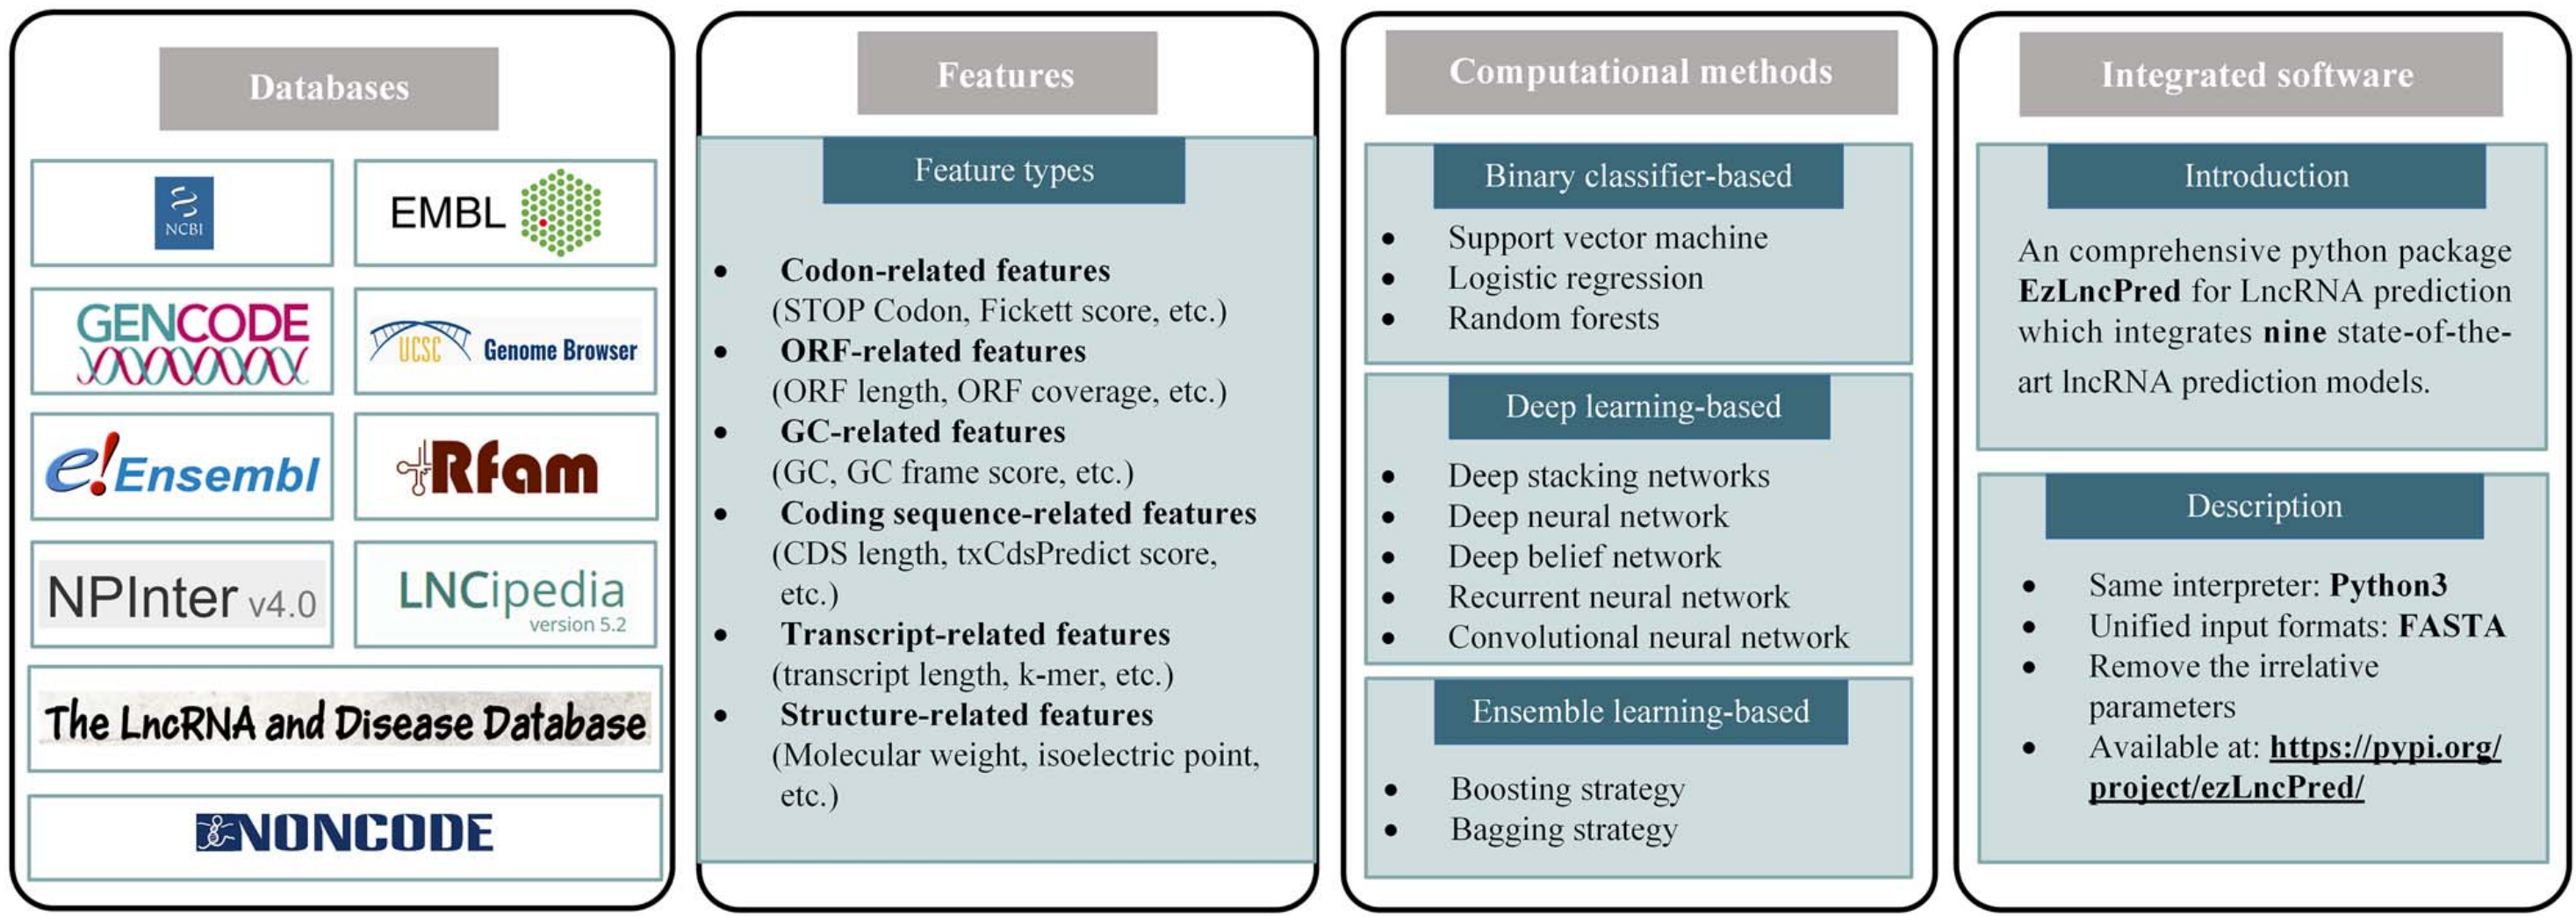
Accurately and rapidly distinguishing long noncoding RNAs (lncRNAs) from transcripts is prerequisite for exploring their biological functions. In recent years, many computational methods have been developed to predict lncRNAs from transcripts, but there is no systematic review on these computational methods. In this review, we introduce databases and features involved in the development of computational prediction models, and subsequently summarize existing state-of-the-art computational methods, including methods based on binary classifiers, deep learning and ensemble learning. However, a user-friendly way of employing existing state-of-the-art computational methods is in demand. Therefore, we develop a Python package ezLncPred, which provides a pragmatic command line implementation to utilize nine state-of-the-art lncRNA prediction methods. Finally, we discuss challenges of lncRNA prediction and future directions.
@article{xu2021systematic, title = {A systematic review of computational methods for predicting long noncoding RNAs}, author = {Xu, Xinran and Liu, Shuai and Yang, Zhihao and Zhao, Xiaohan and Deng, Yaozhen and Zhang, Guangzhan and Pang, Jian and Zhao, Chengshuai and Zhang, Wen}, journal = {Briefings in Functional Genomics}, volume = {20}, number = {3}, pages = {162--173}, year = {2021}, publisher = {Oxford University Press}, } - IJCAI
 CSGNN: Contrastive Self-Supervised Graph Neural Network for Molecular Interaction Prediction.Chengshuai Zhao, Shuai Liu, Feng Huang, and 2 more authorsIn Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, 2021
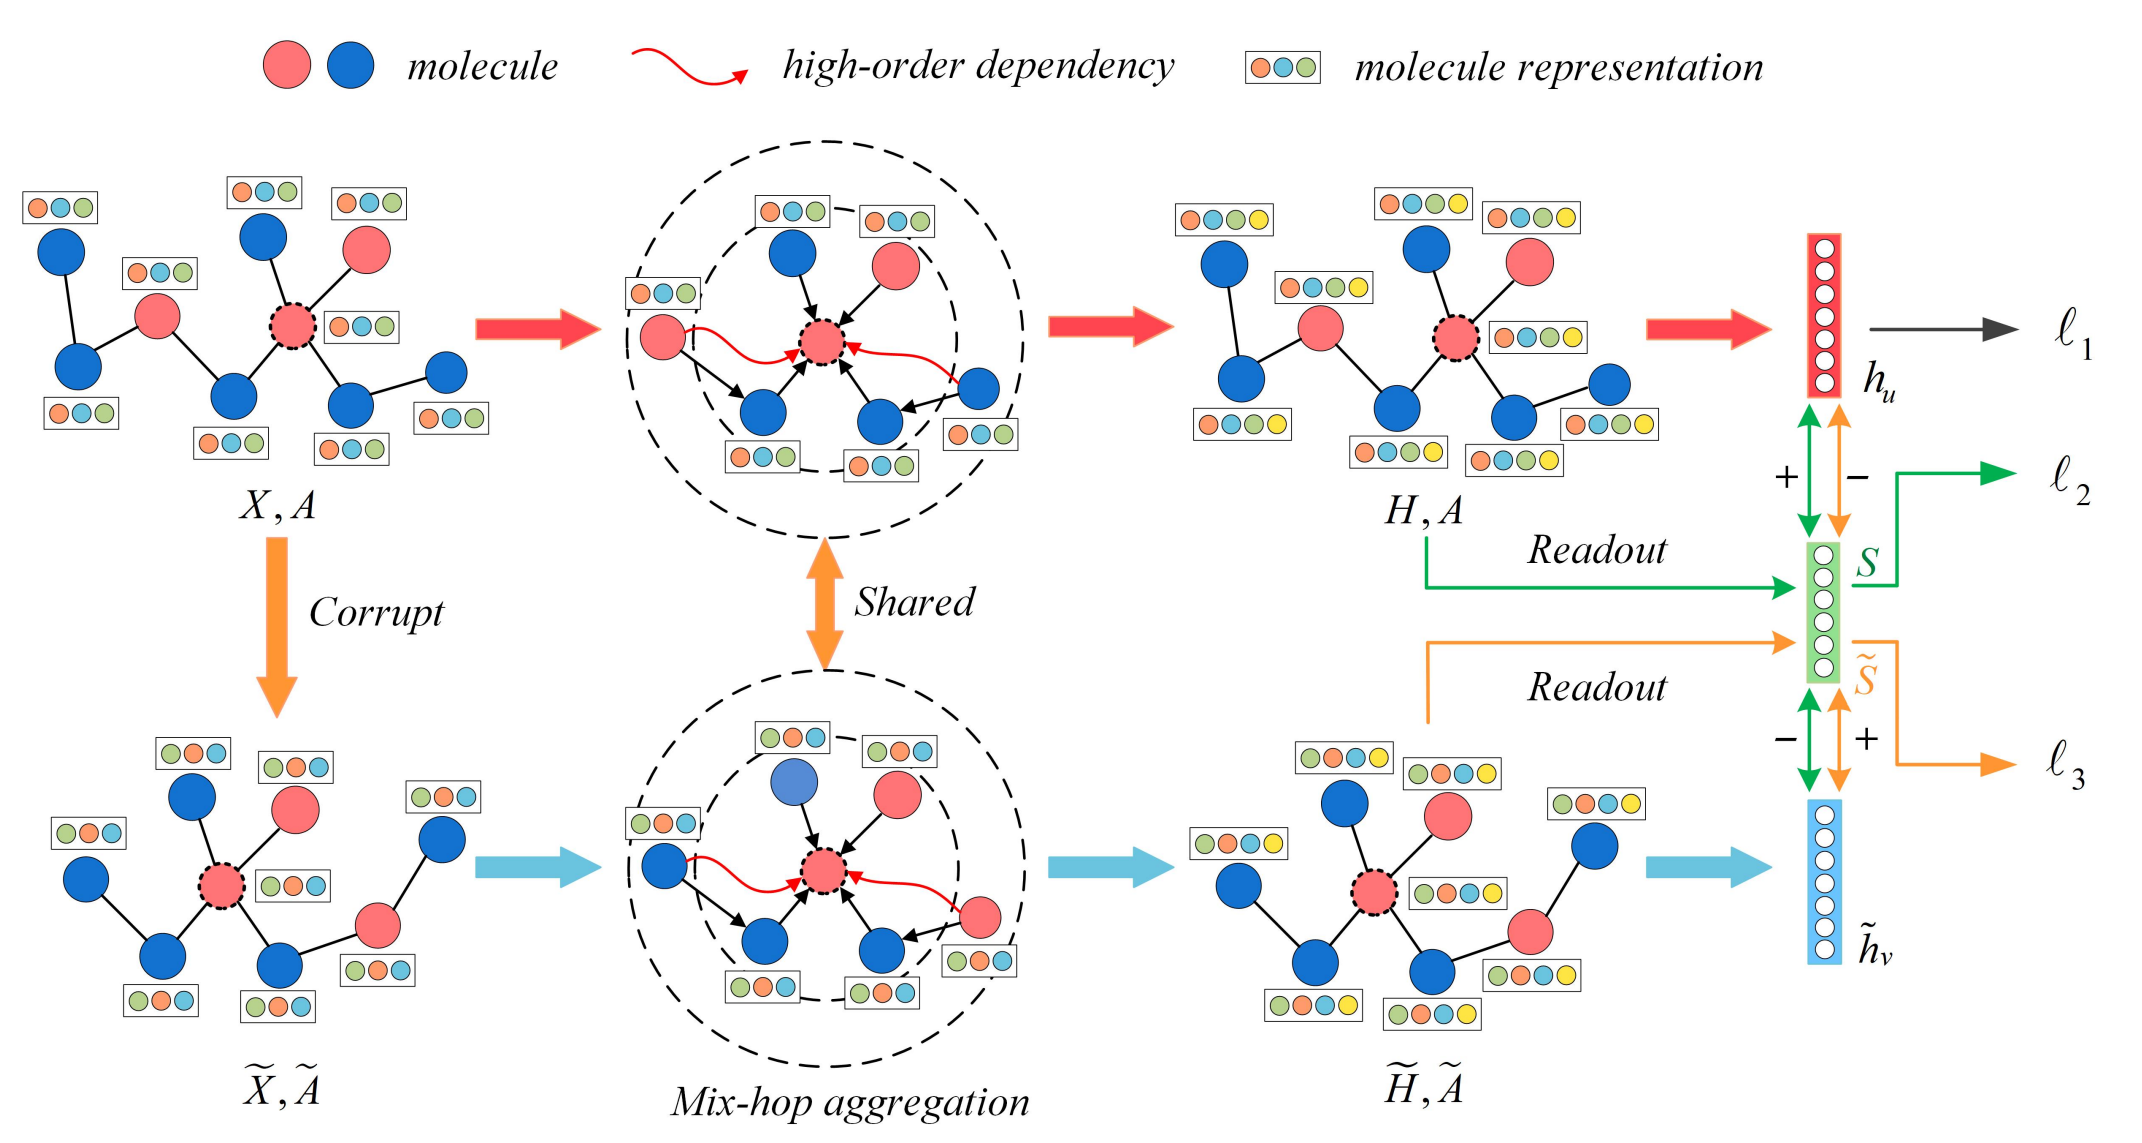
Molecular interactions are significant resources for analyzing sophisticated biological systems. Identification of multifarious molecular interactions attracts increasing attention in biomedicine, bioinformatics, and human healthcare communities. Recently, a plethora of methods have been proposed to reveal molecular interactions in one specific domain. However, existing methods heavily rely on features or structures involving molecules, which limits the capacity of transferring the models to other tasks. Therefore, generalized models for the multifarious molecular interaction prediction (MIP) are in demand. In this paper, we propose a contrastive self-supervised graph neural network (CSGNN) to predict molecular interactions. CSGNN injects a mix-hop neighborhood aggregator into a graph neural network (GNN) to capture high-order dependency in the molecular interaction networks and leverages a contrastive self-supervised learning task as a regularizer within a multi-task learning paradigm to enhance the generalization ability. Experiments on seven molecular interaction networks show that CSGNN outperforms classic and state-of-the-art models. Comprehensive experiments indicate that the mix-hop aggregator and the self-supervised regularizer can effectively facilitate the link inference in multifarious molecular networks.
@inproceedings{zhao2021csgnn,
  title = {CSGNN: Contrastive Self-Supervised Graph Neural Network for Molecular Interaction Prediction.},
  author = {Zhao, Chengshuai and Liu, Shuai and Huang, Feng and Liu, Shichao and Zhang, Wen},
  booktitle = {Proceedings of the Thirtieth International Joint Conference on
                 Artificial Intelligence},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  pages = {3756--3763},
  year = {2021},
}
2020
- Journal
 Graph embedding ensemble methods based on the heterogeneous network for lncRNA-miRNA interaction predictionChengshuai Zhao, Yang Qiu, Shuang Zhou, and 3 more authorsBMC genomics, 2020
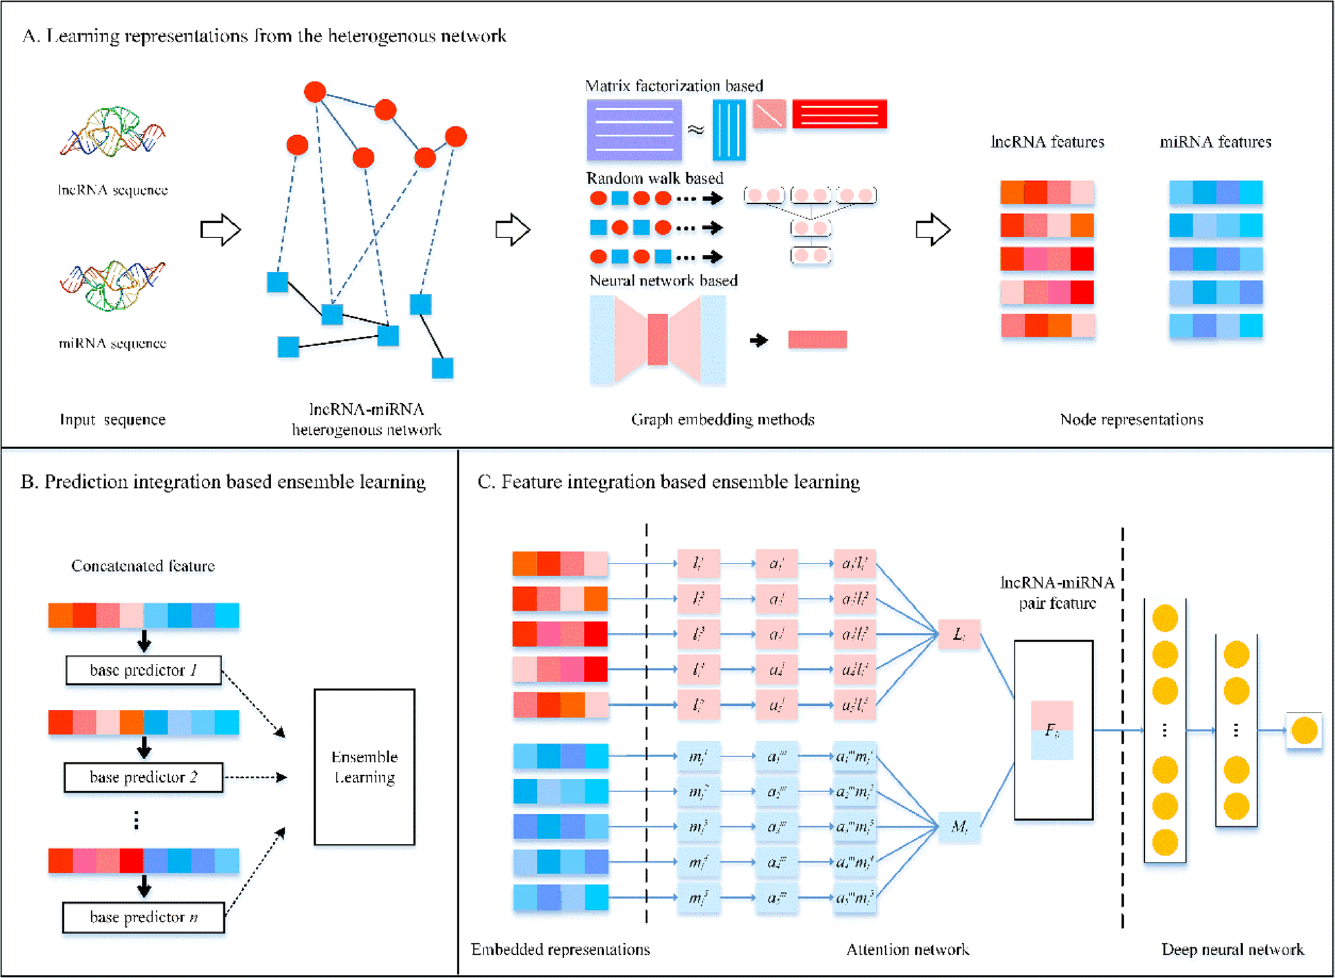
Researchers discover LncRNA-miRNA regulatory paradigms modulate gene expression patterns and drive major cellular processes. Identification of lncRNA-miRNA interactions (LMIs) is critical to reveal the mechanism of biological processes and complicated diseases. Because conventional wet experiments are time-consuming, labor-intensive and costly, a few computational methods have been proposed to expedite the identification of lncRNA-miRNA interactions. However, little attention has been paid to fully exploit the structural and topological information of the lncRNA-miRNA interaction network. In this paper, we propose novel lncRNA-miRNA prediction methods by using graph embedding and ensemble learning. First, we calculate lncRNA-lncRNA sequence similarity and miRNA-miRNA sequence similarity, and then we combine them with the known lncRNA-miRNA interactions to construct a heterogeneous network. Second, we adopt several graph embedding methods to learn embedded representations of lncRNAs and miRNAs from the heterogeneous network, and construct the ensemble models using two ensemble strategies. For the former, we consider individual graph embedding based models as base predictors and integrate their predictions, and develop a method, named GEEL-PI. For the latter, we construct a deep attention neural network (DANN) to integrate various graph embeddings, and present an ensemble method, named GEEL-FI. The experimental results demonstrate both GEEL-PI and GEEL-FI outperform other state-of-the-art methods. The effectiveness of two ensemble strategies is validated by further experiments. Moreover, the case studies show that GEEL-PI and GEEL-FI can find novel lncRNA-miRNA associations. The study reveals that graph embedding and ensemble learning based method is efficient for integrating heterogeneous information derived from lncRNA-miRNA interaction network and can achieve better performance on LMI prediction task. In conclusion, GEEL-PI and GEEL-FI are promising for lncRNA-miRNA interaction prediction.
@article{zhao2020graph,
  title = {Graph embedding ensemble methods based on the heterogeneous network for lncRNA-miRNA interaction prediction},
  author = {Zhao, Chengshuai and Qiu, Yang and Zhou, Shuang and Liu, Shichao and Zhang, Wen and Niu, Yanqing},
  journal = {BMC genomics},
  volume = {21},
  number = {13},
  pages = {1--12},
  year = {2020},
  publisher = {BioMed Central},
}